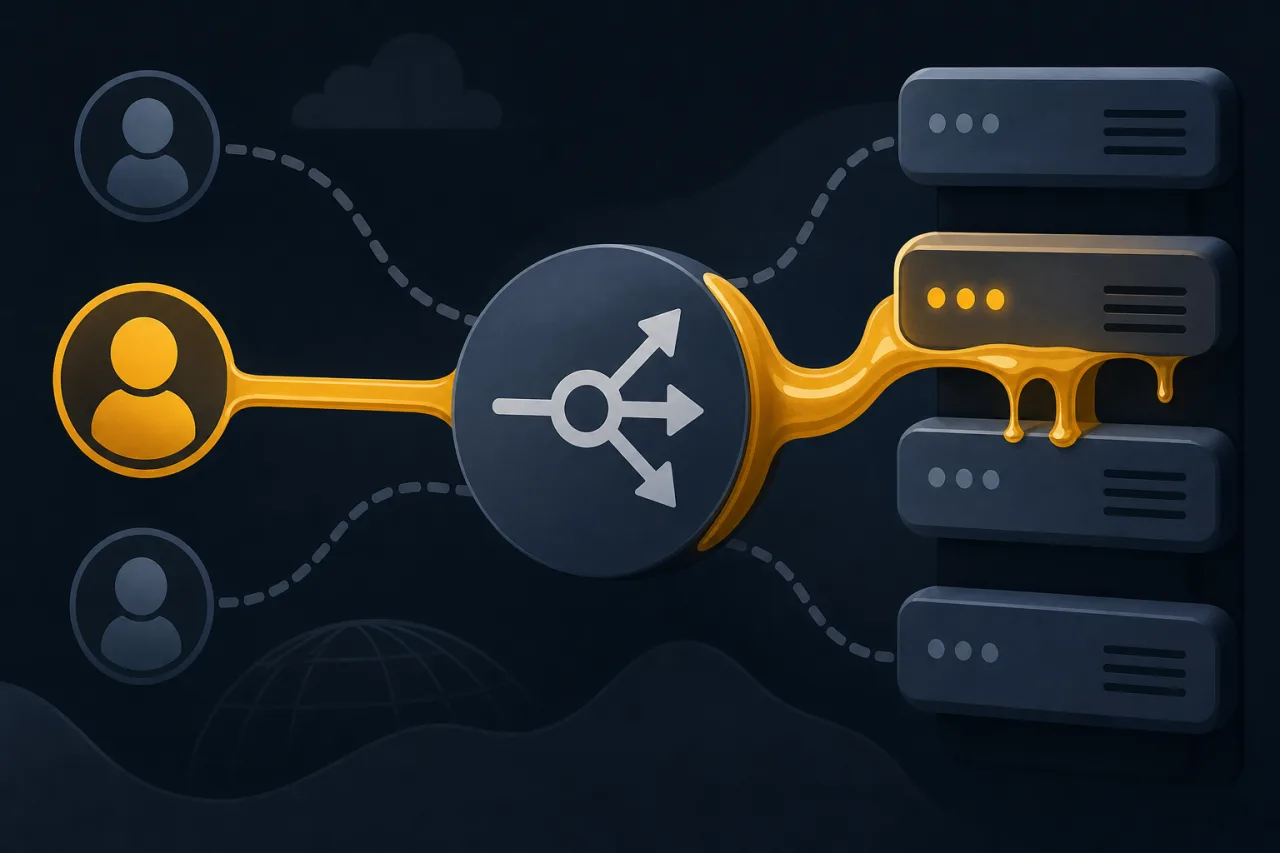
What Are Sticky Sessions?
Sticky sessions (also called session affinity) tell a load balancer to route every request from a given client to the same backend server for the duration of a session. The load balancer typically tracks this via a cookie it injects (AWSALB, JSESSIONID, or a custom value) or by hashing the client's IP address.
Without stickiness, a round-robin or least-connections balancer can send consecutive requests from the same user to different backends — which is usually fine, but breaks down the moment your application stores state locally on the server.
When You Actually Need Sticky Sessions
In-memory session storage
The classic case: your app stores the authenticated user's session in the server process's memory (or in a local file like PHP's default session handler). If request two lands on a different node, that node has no record of the session and the user gets logged out or hit with an error.
Stateful WebSocket connections
A WebSocket connection is a persistent TCP connection to one server. If your load balancer doesn't maintain affinity, a reconnect after a network hiccup might land on a different node that has no context for that socket's state.
Long-running upload or streaming jobs
Some apps accumulate chunks of a large upload in local temp storage before finalising. Switching backends mid-upload corrupts the transfer.
Legacy software you can't change
Sometimes the app is a black box. Sticky sessions are the pragmatic escape hatch when you can't refactor the state management.
When Sticky Sessions Hurt You
Stickiness is a workaround, not a feature. It trades one set of problems for another.
Uneven load distribution. If you pin users to backends by cookie or IP, a small number of active power users can overwhelm one node while others sit idle. Least-connections routing loses most of its value.
Harder failover. When a pinned backend crashes, all its sessions die simultaneously. Without stickiness those users would have been spread across nodes anyway — the blast radius per node is smaller.
Deployment complexity. Rolling restarts cycle nodes in and out. Sticky sessions mean users get bounced at restart time, or you have to drain connections carefully with longer maintenance windows.
Debugging gets harder. A bug reproducible only on node 3 is invisible in your aggregated logs unless you tag requests with the backend that handled them.
It masks the real problem. If you need stickiness, you probably have a state management problem worth fixing at the application layer.
The Better Alternatives
Before reaching for sticky sessions, consider these approaches:
- Centralised session store — Redis or Memcached with a shared session store is the most common fix. Every node can read and write session data; no affinity needed.
- JWT or signed cookies — Push session state to the client. The token is stateless from the server's perspective and any backend can verify it.
- Database-backed sessions — Slower than in-memory stores but dead simple and works with any stack.
- Sticky sessions scoped to WebSocket only — Many modern load balancers (NGINX, HAProxy, AWS ALB) let you apply affinity to specific routes. Keep HTTP requests stateless and only pin the
/wspath.
Configuring Sticky Sessions Safely (If You Must)
If you've weighed the options and stickiness is the right call, do it deliberately:
- Use cookie-based affinity, not IP hashing. IP hashing breaks for users behind NAT or a corporate proxy — thousands of users share one IP. ALB, NGINX, and HAProxy all support cookie-based stickiness.
- Set a sensible cookie TTL. Match it to your session lifetime. A one-week sticky cookie on a 30-minute session is a footgun.
- Enable connection draining. Give in-flight sessions time to finish (30–60 seconds is common) before a node is pulled from rotation during deployments or health-check failures.
- Monitor per-node request rates separately. Aggregate metrics hide hot spots. Alert if one backend's request rate is more than 2× the mean.
- Test failover explicitly. Kill a backend node in staging and verify the load balancer redistributes sessions gracefully.
How Uptime Monitoring Intersects Here
A synthetic request may not carry the same session cookie as a returning user. Test fresh sessions and established sessions separately when diagnosing affinity failures.
Key Takeaways
- Sticky sessions exist to paper over server-side state; they're a workaround, not an architecture.
- Use a centralised session store (Redis, etc.) to eliminate the need for affinity entirely.
- If you must use stickiness, prefer cookie-based over IP-hash, and always configure connection draining.
- Stickiness makes failover worse and load distribution uneven — monitor per-node metrics, not just totals.
- WebSocket affinity can often be scoped to just that route, keeping the rest of your traffic stateless.