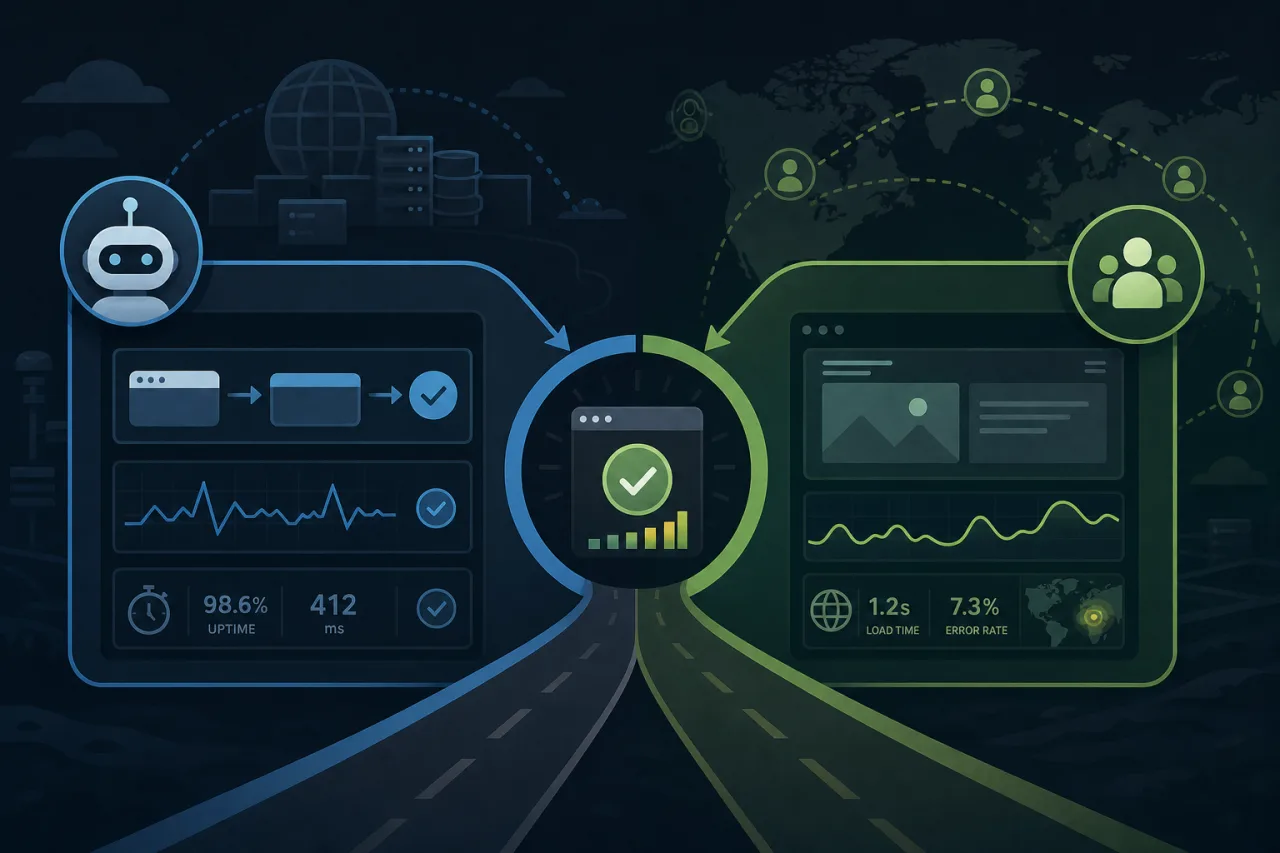
Synthetic monitoring runs scheduled tests against a service. Real-user monitoring (RUM) records what visitors' browsers experience. Use synthetic checks to test availability and selected workflows even when traffic is quiet. Use RUM to find slow or broken experiences among the visits your instrumentation captures.
Both have gaps. A passing homepage check can miss a broken checkout button. A browser that cannot load your site may never run the RUM script. Build your monitoring around a specific user task, then decide what evidence each tool can collect.
Separate HTTP checks from browser tests
An HTTP check makes a request and evaluates the response. It can detect connection failures, unexpected status codes or missing content. It does not execute the page's JavaScript or prove that a visitor can complete a purchase.
A browser synthetic test can load the page, interact with controls and check the resulting state. AWS describes Synthetics canaries as scheduled scripts that can follow customer actions without customer traffic. The script still covers only the actions and conditions you specify.
Choose an assertion that proves the step worked. Clicking a button successfully establishes that the test could click it. Checking that the expected confirmation appeared establishes more. Playwright's assertions can retry a condition until it passes or reaches its timeout; a fixed sleep alone gives you no success condition.
A repeatable script helps compare runs, but routes, CDN caches and the service itself can change underneath it. A synthetic alert can arrive before the next visitor encounters a fault. It can also arrive after visitors have already failed. Schedule, execution time and alert policy determine that delay.
What RUM captures, and what it misses
Web RUM normally uses client instrumentation to send performance and error events to a collector. The available events depend on the SDK, browser support and configuration. For example, CloudWatch RUM collects page-load performance and client-side errors in near real time. RUM can support alerting; it is not limited to weekly performance reports.
Treat the result as a view of captured visits. Sampling, consent choices, blocked scripts and failed event uploads can change which visitors appear. Google's comparison of CrUX and RUM explains how different populations and measurement windows produce different results. A falling error rate is weak evidence of recovery if the number of reporting visits has also collapsed.
Business outcomes need their own definitions. Recording a page view or a button click does not establish that an order was accepted. Decide which event means success, and reconcile it with the server-side result where possible. Session replay is a separate capability that some RUM products provide; collecting timing metrics does not automatically record every journey.
For a hypothetical shop, the coverage might look like this. These are test-design examples, not Pingy incident results.
| Signal | What it establishes |
|---|---|
| HTTP response | The selected URL answered with the expected status or content. |
| Browser assertion | The scripted action reached its expected visible result. |
| RUM event | An instrumented visit reported a defined observation. |
| Order record | The backend recorded the transaction under its own success rules. |
Keep these signals separate in reports. Each has a different population and failure boundary.
Compare the same metric
An HTTP response time and Largest Contentful Paint (LCP) measure different things. LCP concerns when the largest eligible visible image or text block renders. A quick response can still be followed by slow JavaScript, fonts or images. Compare browser LCP with browser LCP when investigating rendering, and inspect request timing separately.
A lab run also has a chosen device, network profile and cache state. Field data contains a distribution of experiences. Google's lab and field guide explains why viewport, personalization and caching can change the measured result. A browser synthetic can test slower devices or returning visits if configured to do so. It cannot establish how common those conditions are among your visitors.
Interaction to Next Paint (INP) measures responsiveness to clicks, taps and keyboard interactions over a page visit. It does not measure how long a purchase takes to finish. A visit without a qualifying interaction may have no INP value; that absence is not a zero-millisecond result. See Google's INP definition.
Before comparing dashboards, align the page or route, device group, browser, time window and metric definition. Show the sample count beside the percentile. Sparse segments can move sharply after a few observations, so keep an explicit insufficient-data state.
CrUX is another field dataset with its own eligibility and aggregation rules. It includes eligible Chrome experiences and imposes page and origin requirements. It is not a census of your visitors, and it should not be treated as a live outage detector.
Build one useful checkout check
Start with one important path and write down exactly what a successful run proves. This hypothetical checkout plan avoids placing a real order:
- Open a product page using a dedicated test account or an anonymous session, as the flow requires. Fix the browser, viewport and starting cookie state so later changes are interpretable.
- Add a test item and assert that the cart contains the expected item and quantity. If the application shows an error, fail the check even if every HTTP request returned 200.
- Open checkout and assert that the expected total and payment form appear. Record the failed step and enough request detail to investigate it.
- Stop before purchase submission. Document that payment authorization, order creation and fulfillment remain outside this check. Test those separately in an approved environment or with a controlled transaction and cleanup process.
Keep credentials in the runner's secret store. Review screenshots and logs for personal information. Give the test an owner who can distinguish a broken selector or expired test account from a customer-facing fault.
Then instrument the corresponding real flow. Define cart, checkout and purchase-result events with the application team. Use normalized route names and release identifiers to group results; avoid sending tokens, form contents or raw URLs containing private values. Verify the actual outgoing payload and collector receipt in a test session.
Metric collection needs testing too. The web-vitals library documentation explains that callbacks can report again during a visit or after a back/forward-cache restore. Follow the library's metric-ID and update semantics so repeated reports do not become extra independent visits. Test backgrounding and returning to the page, along with the browsers your users rely on.
Investigate disagreements before clearing an alert
Line up the failed step, release and observation time first. Geographic proximity alone does not prove that a synthetic runner and a visitor used the same ISP, address family or CDN edge. Use the multi-region monitoring guide to interpret location differences.
The table below gives investigation starting points. None of these combinations establishes a root cause by itself.
| Observation | Next check |
|---|---|
| HTTP passes; browser fails | Inspect the assertion, scripts, API calls and test account. |
| Synthetic passes; RUM worsens | Compare affected routes, devices, releases and sample counts. |
| Synthetic fails; RUM looks healthy | Check test scope and whether affected visitors can report. |
| RUM volume drops | Check traffic, consent, SDK loading and collector health. |
| Both report failures | Match the operation and time window, then inspect server evidence. |
A working synthetic should not suppress a RUM alert about an untested browser group. Healthy RUM should not clear a failed synthetic when the affected visitors may be missing from the sample. Keep detection separate from notification grouping, as described in the alert-fatigue guide.
For Pingy, start with the regional response-time report to investigate HTTP reachability and timing. Add browser transaction checks and client instrumentation for the outcomes that require them. Before accepting the setup, deliberately break one assertion in a test environment and block the RUM collector there. Verify that a failed user step and missing telemetry produce different, visible results.