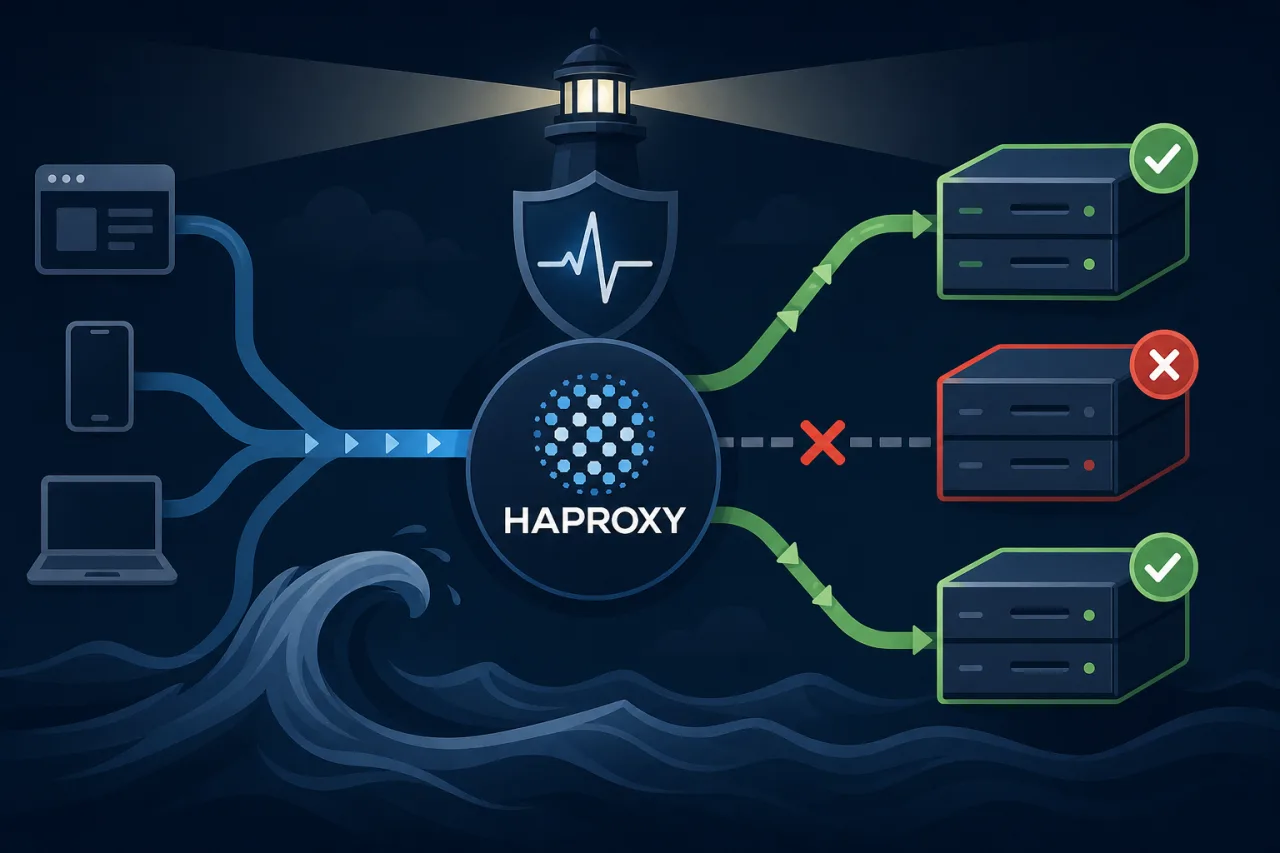
Why Passive Balancing Isn't Enough
Round-robin and least-connections algorithms distribute load, but they don't know whether a backend is actually serving requests successfully. A process can be listening on port 443 while returning 500s, exhausting database connections, or hanging on every request. Health checks close that gap by actively probing backends and removing unhealthy ones from the pool before users notice.
How HAProxy Health Checks Work
HAProxy supports three levels of checking:
- TCP checks – confirms the port accepts a connection. Fast, but blind to application state.
- HTTP checks – sends a real HTTP request and evaluates the status code. Catches application-level failures.
- Agent checks – a sidecar process on the backend returns weight or state strings (
ready,drain,down). Useful for graceful drains during deploys.
For most web services, HTTP checks are the right default.
Basic HTTP Health Check Configuration
Below is a minimal but production-usable haproxy.cfg backend block:
backend web_servers
    balance roundrobin
    option httpchk GET /healthz HTTP/1.1\r\nHost:\ api.example.com
    http-check expect status 200

    default-server inter 5s fall 3 rise 2 timeout connect 2s timeout server 5s

    server web1 10.0.1.10:8080 check
    server web2 10.0.1.11:8080 check
    server web3 10.0.1.12:8080 check backup
Key directives explained
option httpchk– enables HTTP-mode checks and defines the request line. Always include theHostheader if your backend uses virtual hosting.http-check expect status 200– only a200marks the backend healthy. You can usestatus 200-204orrstatus ^2for a range.inter 5s– check interval. Five seconds is a reasonable starting point; reduce to 2s for latency-sensitive services.fall 3– three consecutive failures before the server is marked DOWN. Prevents a single slow check from causing a flap.rise 2– two consecutive successes before a server is restored to rotation.backup– marksweb3as a standby that only receives traffic when all primary servers are down.
Designing a Useful /healthz Endpoint
A health endpoint that just returns 200 OK immediately is better than nothing, but not by much. A meaningful check should verify the dependencies the backend actually needs:
- Database connectivity – run a lightweight query (
SELECT 1). - Cache reachability – ping Redis or Memcached.
- Disk space – fail if free space drops below your threshold.
- External dependencies – only include ones that are truly blocking; don't fail health for a non-critical third-party API.
Return 200 when everything is operational, 503 when the node should leave rotation. Keep the response time under 500 ms; HAProxy's check timeout applies here too.
Failover in Practice
When fall 3 consecutive checks fail against web1, HAProxy immediately stops routing new connections to it. In-flight connections are not killed — HAProxy waits for them to complete naturally (or for the server timeout to fire). The remaining healthy servers absorb the load.
If all primary servers fail, web3 (the backup) takes traffic. This gives you a meaningful last-resort response — perhaps a maintenance page or a read-only mode — rather than a connection refused.
Watching it happen
Enable the stats socket to inspect state without restarting:
global
    stats socket /run/haproxy/admin.sock mode 660 level admin
Then query it:
echo "show servers state web_servers" | socat stdio /run/haproxy/admin.sock
The output shows each server's current state (UP, DOWN, MAINT), check results, and weight.
Pairing HAProxy Checks with External Monitoring
HAProxy health checks catch failures at the load balancer. They won't tell you if the load balancer itself is unreachable, if DNS is broken, or if an entire region has gone dark. External uptime monitoring — probing your public endpoints from multiple geographic locations — fills that blind spot. Services like Pingy can alert you when the URL your users actually hit stops responding, independent of what HAProxy thinks is healthy internally. The two layers are complementary, not redundant.
Tuning Checklist
-
interis short enough to catch failures before users do (≤10s for most services) -
fallis high enough to avoid flapping on a single slow check (≥2) -
riseis conservative enough that a flapping server doesn't bounce back immediately (≥2) -
/healthzchecks real dependencies, not just process liveness - A
backupserver or maintenance page exists for total-pool failure - Stats socket is enabled so you can inspect server state without a reload
- External monitoring covers the public endpoint, not just internal IPs
Key Takeaways
- TCP checks confirm reachability; HTTP checks confirm application health — use HTTP checks for web services.
fallandrisethresholds prevent flapping without sacrificing detection speed.- A well-designed
/healthzendpoint is as important as the HAProxy configuration itself. - The
backupdirective gives you a controlled degraded state instead of a hard failure. - HAProxy health checks and external uptime monitoring solve different problems; you need both.