Tutorials
Practical guides on uptime, monitoring, DRaaS, load balancing and AWS reliability from Pingy.io. Tracking an incident? See Outage Reports.
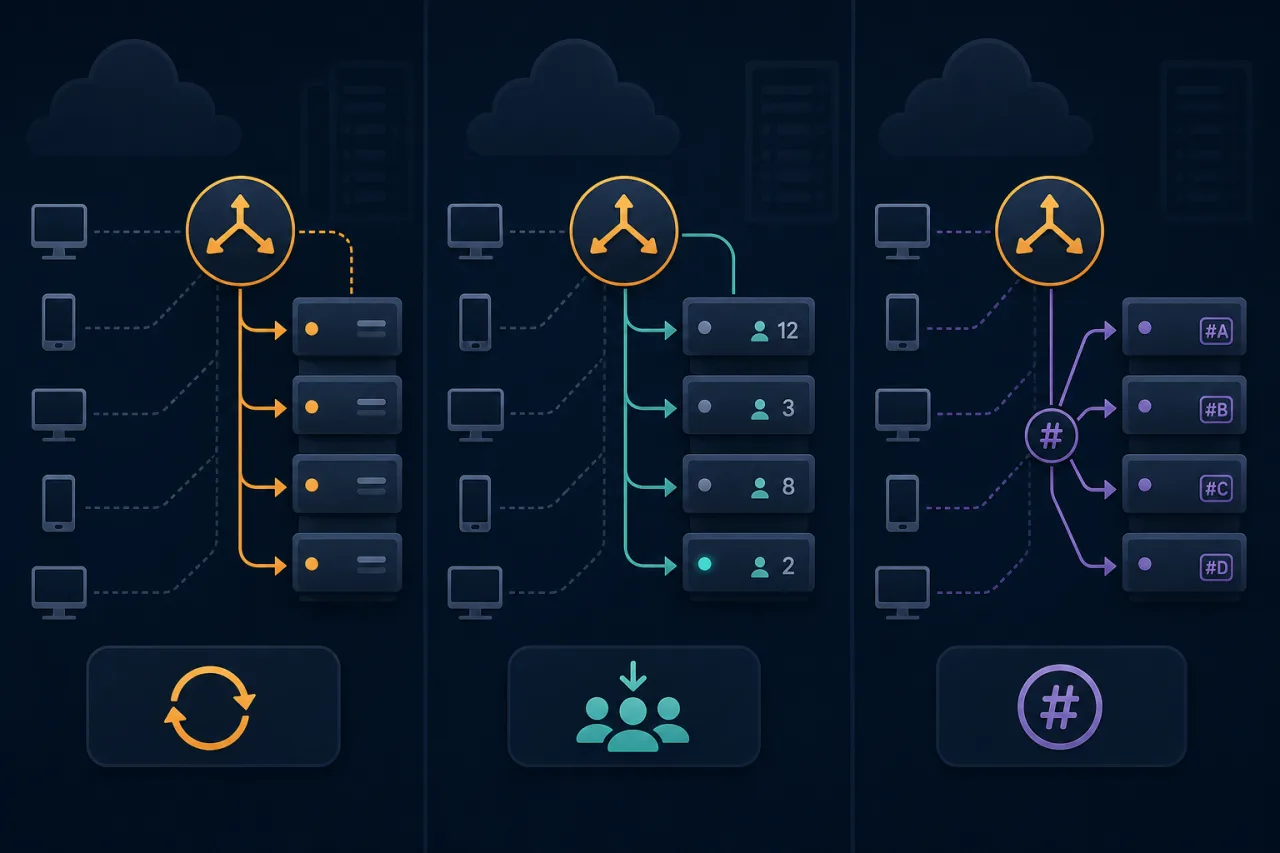
Load-balancing algorithms you can test with NGINX
Compare round-robin, least connections and hashing with a tested NGINX configuration, measured routing results and a backend failure drill.
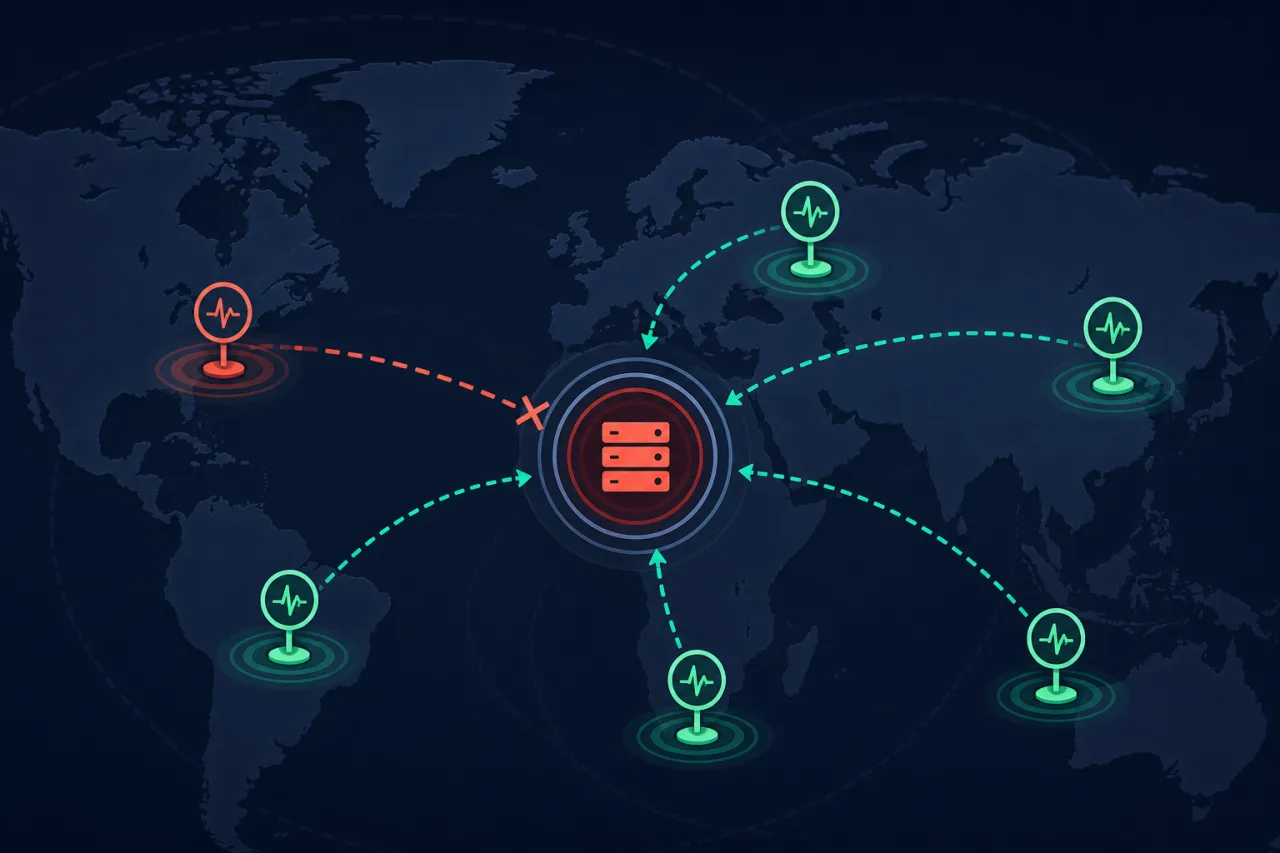
Multi-region monitoring: probes, quorum and regional failures
Choose useful probe locations, interpret conflicting results, and test alert delays without hiding regional failures.
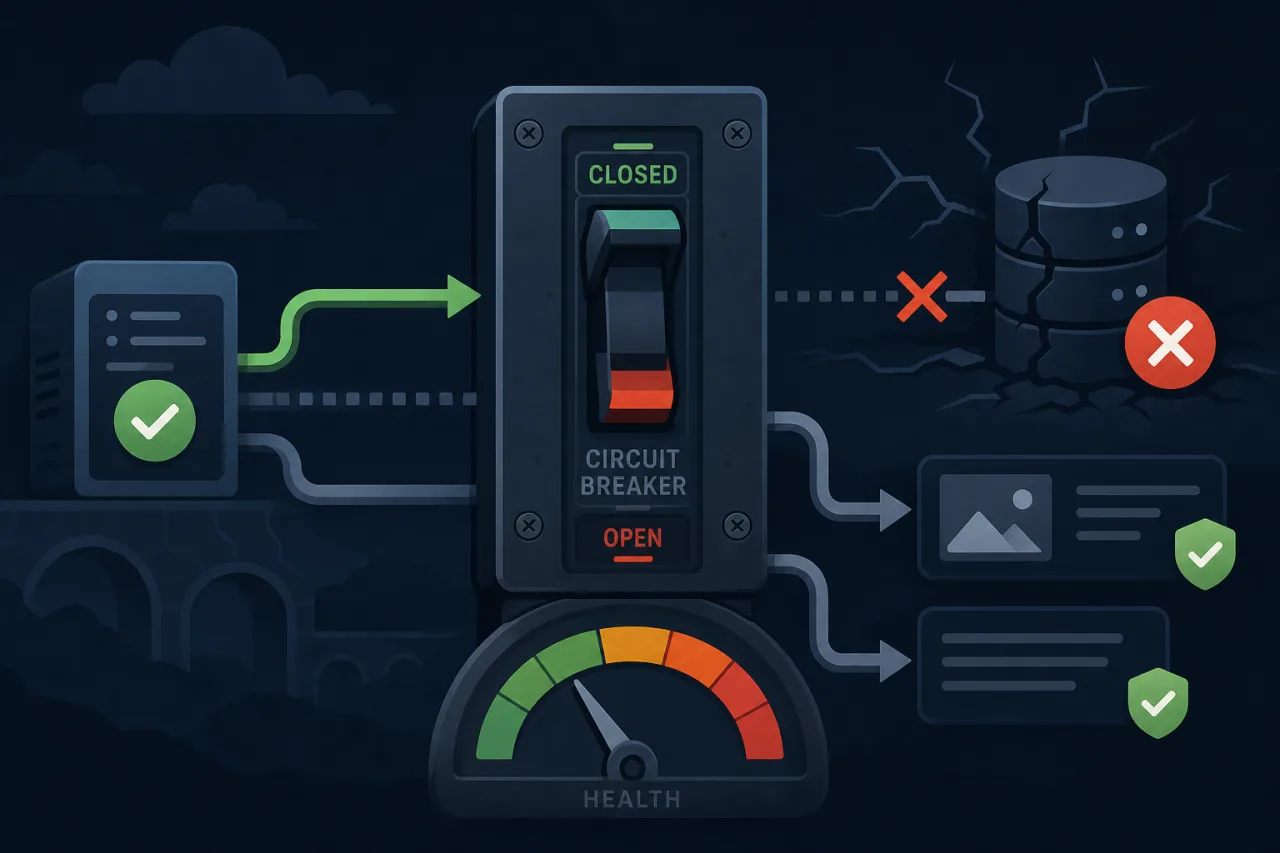
Circuit breakers and graceful degradation under failure
Define safe fallbacks, bound slow calls, and test how circuit breakers open and recover across application instances.
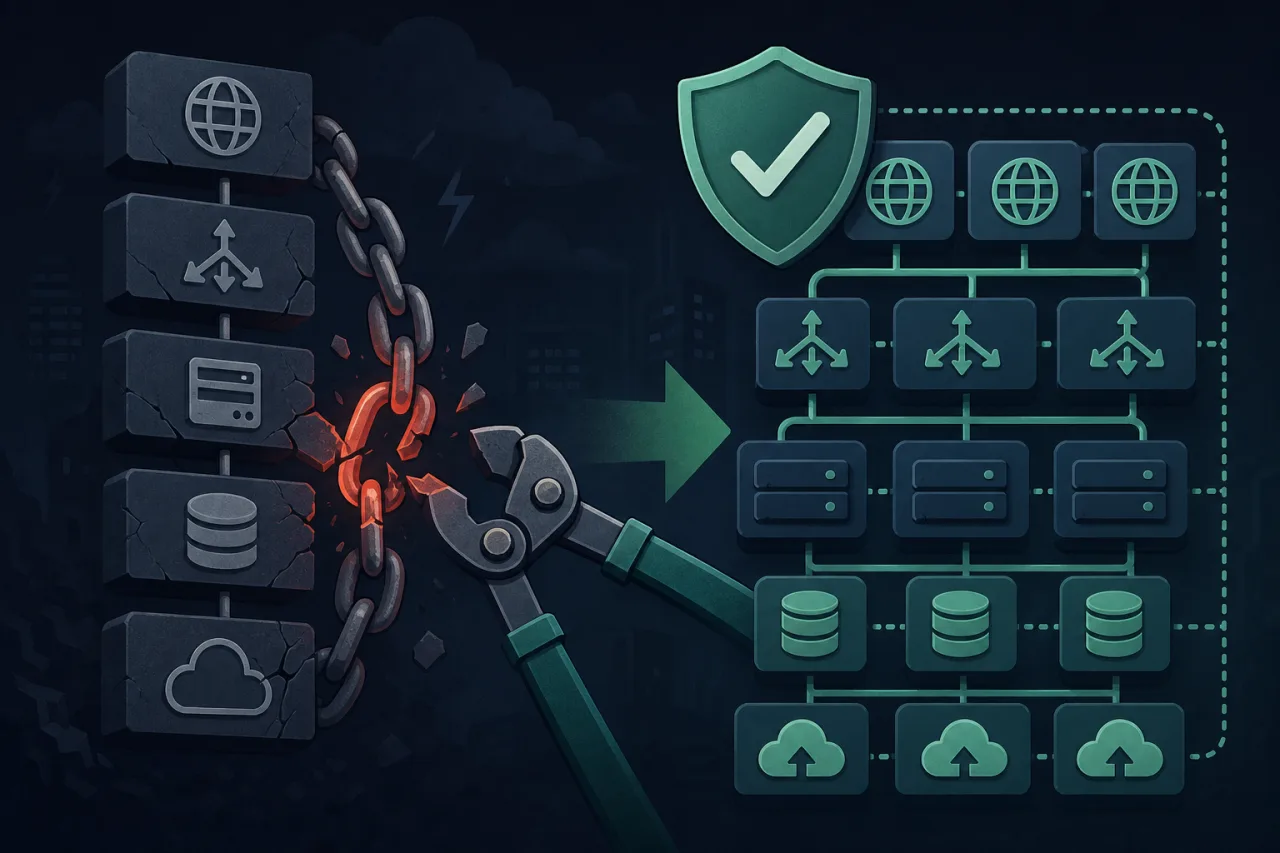
Find single points of failure in your web stack
Trace shared dependencies, check spare capacity and test safe failover across DNS, databases, caches and application servers.
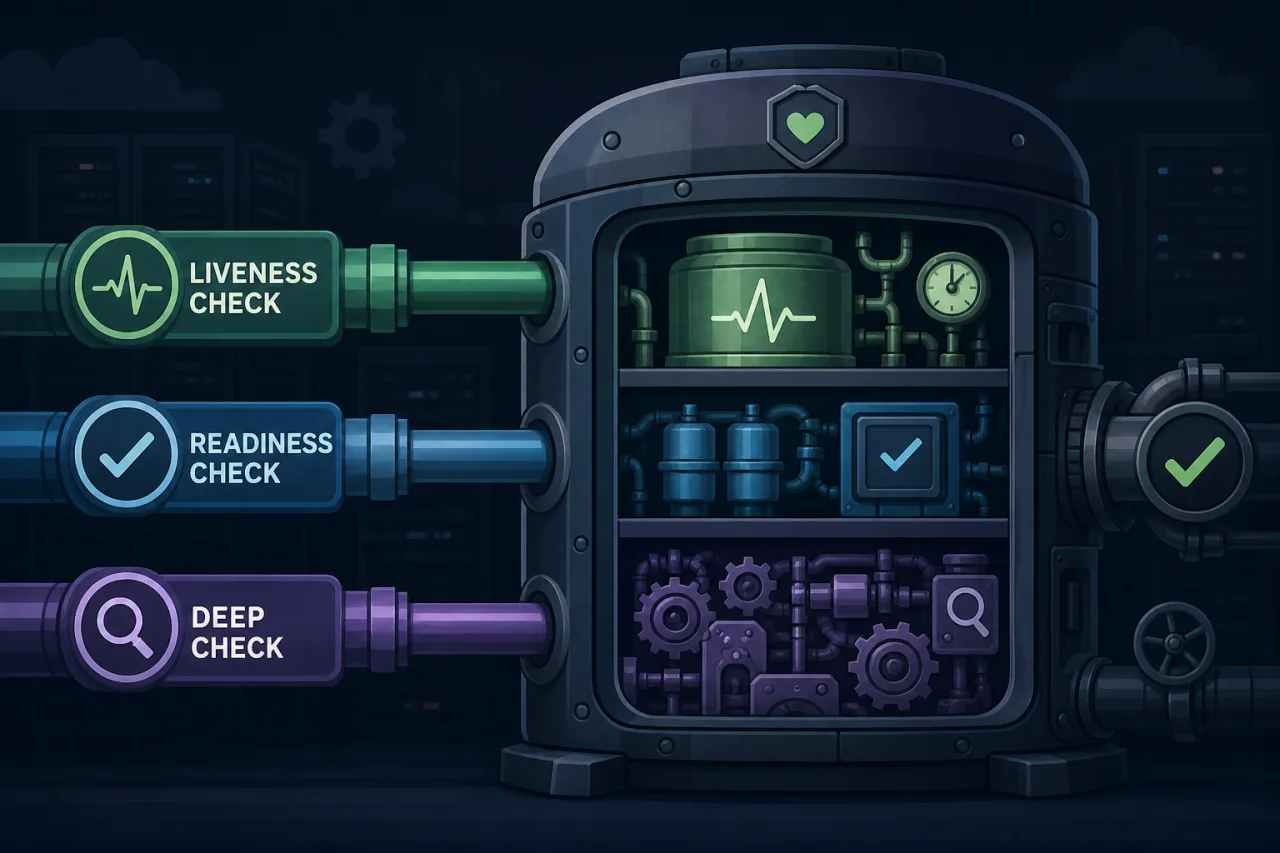
Liveness, readiness and deep health checks
Define what each health check controls, handle shared dependency failures, and test startup, recovery and shutdown before enabling automatic action.
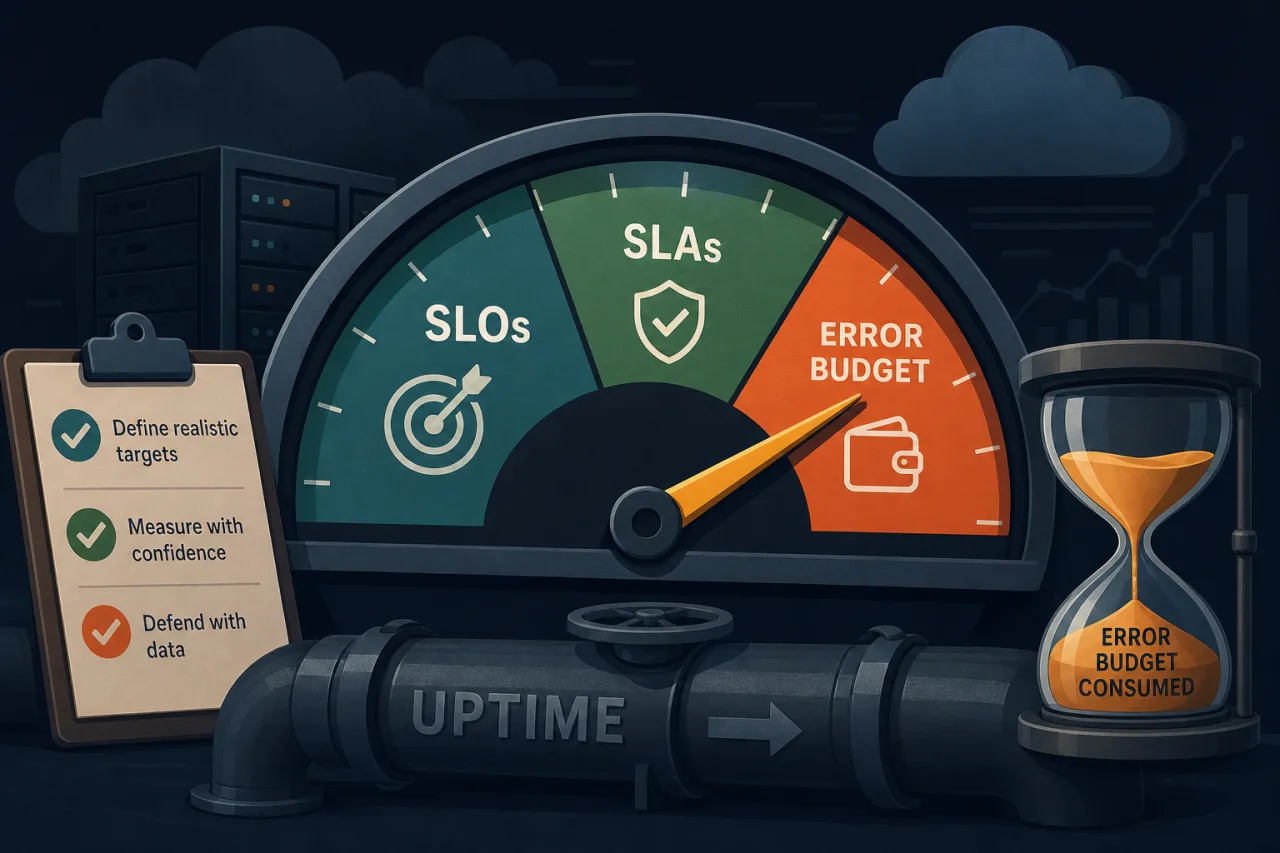
SLOs, SLAs and error budgets you can measure
Define a useful SLO, calculate request and downtime budgets correctly, and use burn rates to decide when failures need attention.
How to Design for Five-Nines (99.999%) Uptime
A practical engineering guide to the architecture, tradeoffs, and operational discipline required to hit 99.999% availability.