Tutorials
Practical guides on uptime, monitoring, DRaaS, load balancing and AWS reliability from Pingy.io. Tracking an incident? See Outage Reports.
On-Call Rotations That Don't Burn People Out
A practical guide to structuring on-call schedules, escalation policies, and recovery time so engineers stay alert, effective, and willing to stay on the team.
Writing a Blameless Post-Mortem That Actually Helps
A practical guide to running post-mortems that surface real system insights instead of assigning blame and getting filed away.
Status Pages: How to Communicate During an Incident
A practical guide to running a status page that actually helps your users during an outage—what to post, when to post it, and how to avoid the common mistakes that erode trust.
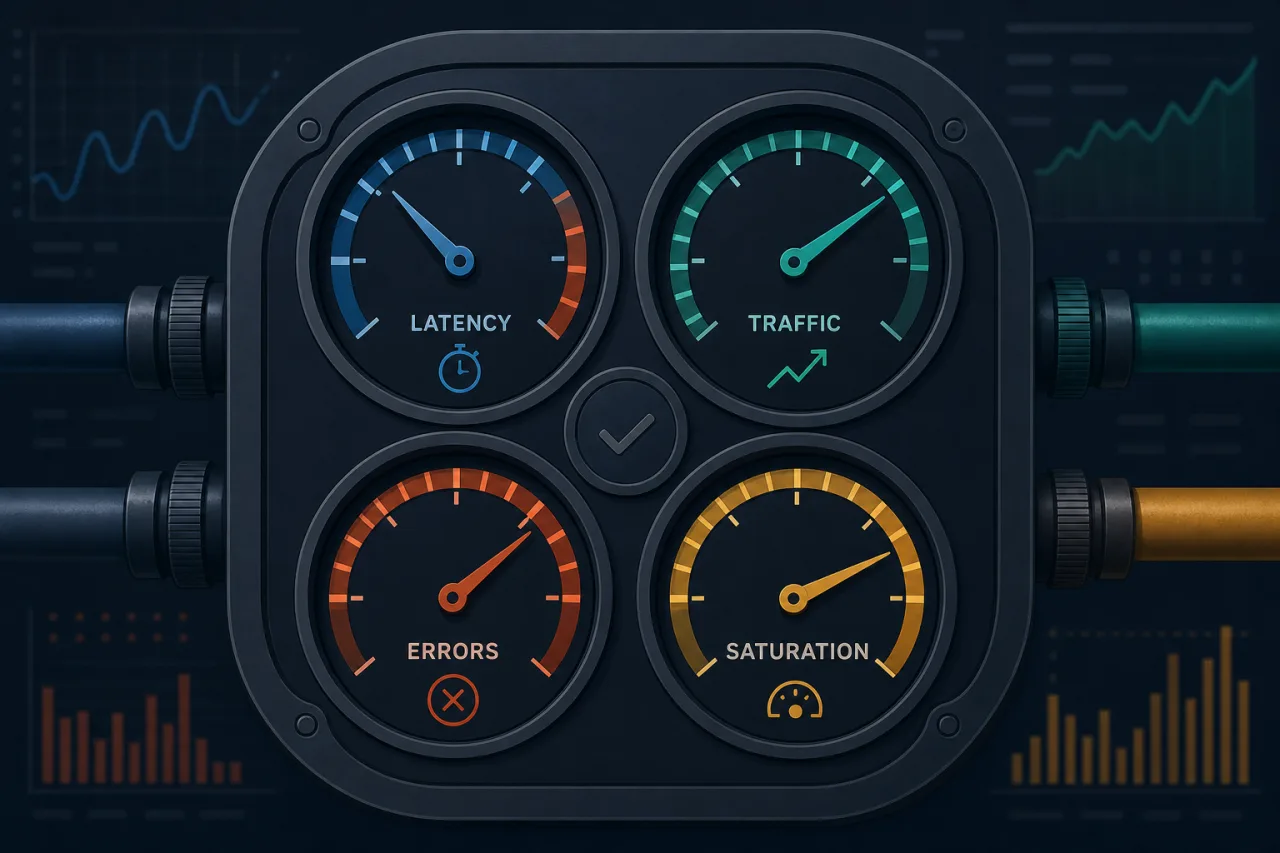
The Four Golden Signals of Monitoring
A practical guide to latency, traffic, errors, and saturation — the four metrics every production system needs to instrument first.
Reducing Alert Fatigue with Smart Thresholds and Flap Damping
How to cut through the noise by tuning alert thresholds and suppressing transient failures before they wake someone up at 3 a.m.
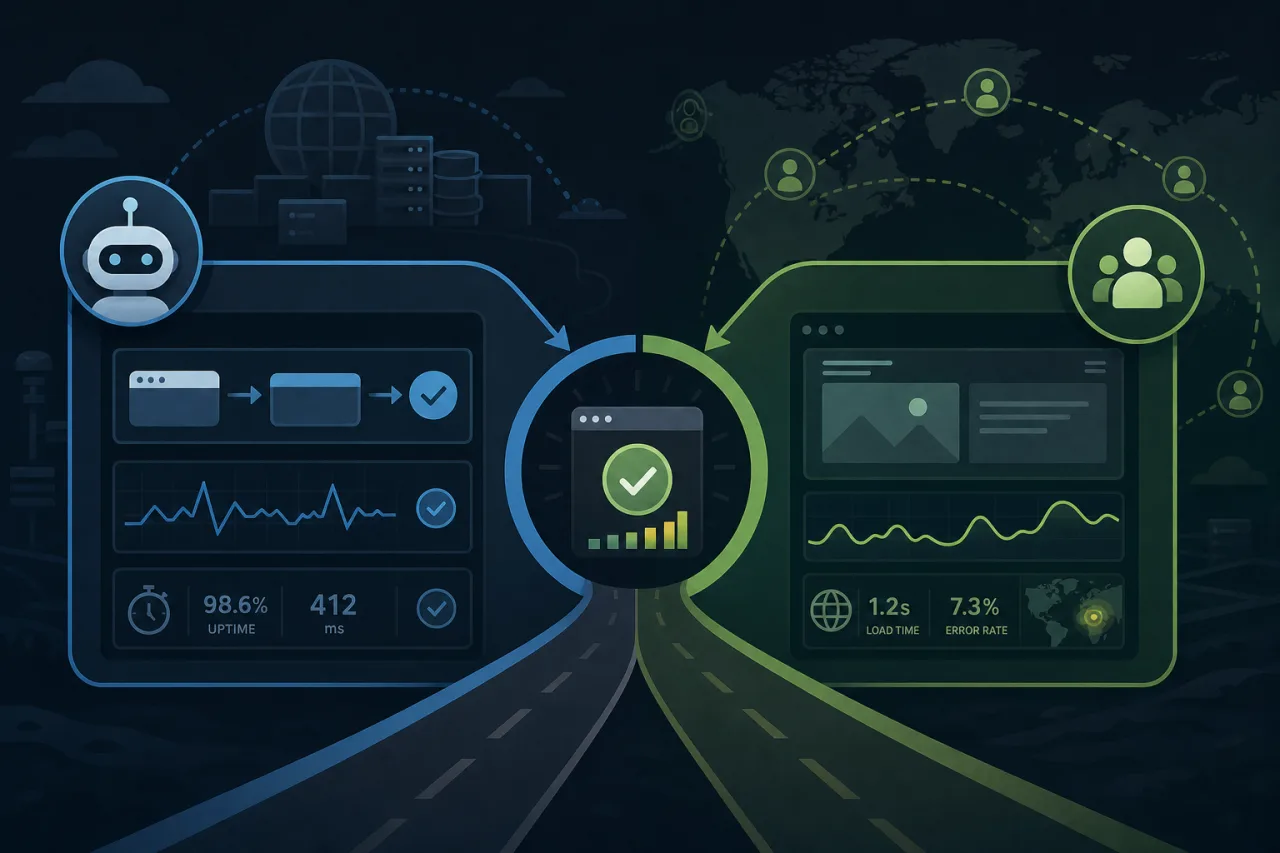
Synthetic Monitoring vs Real-User Monitoring (RUM): Choosing the Right Tool for the Job
A practical breakdown of how synthetic and real-user monitoring differ, when to use each, and how to combine them for complete visibility into your application's health.
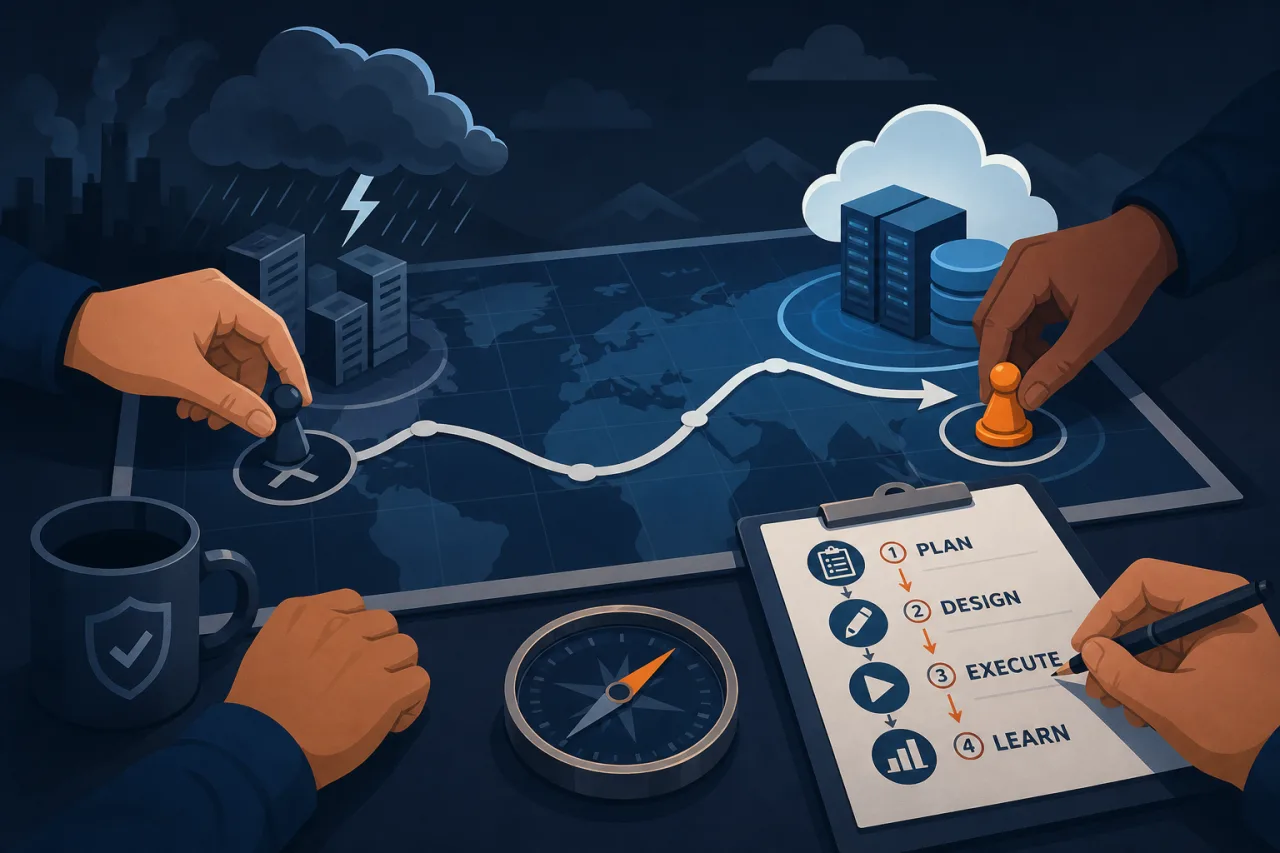
How to Run a Disaster-Recovery Game Day
A step-by-step guide to designing, executing, and learning from a DR game day so your team knows what to do before the real incident hits.
Building a Warm-Standby Disaster Recovery Site
A practical guide to designing, provisioning, and validating a warm-standby DR environment that can take live traffic without a cold-start scramble.
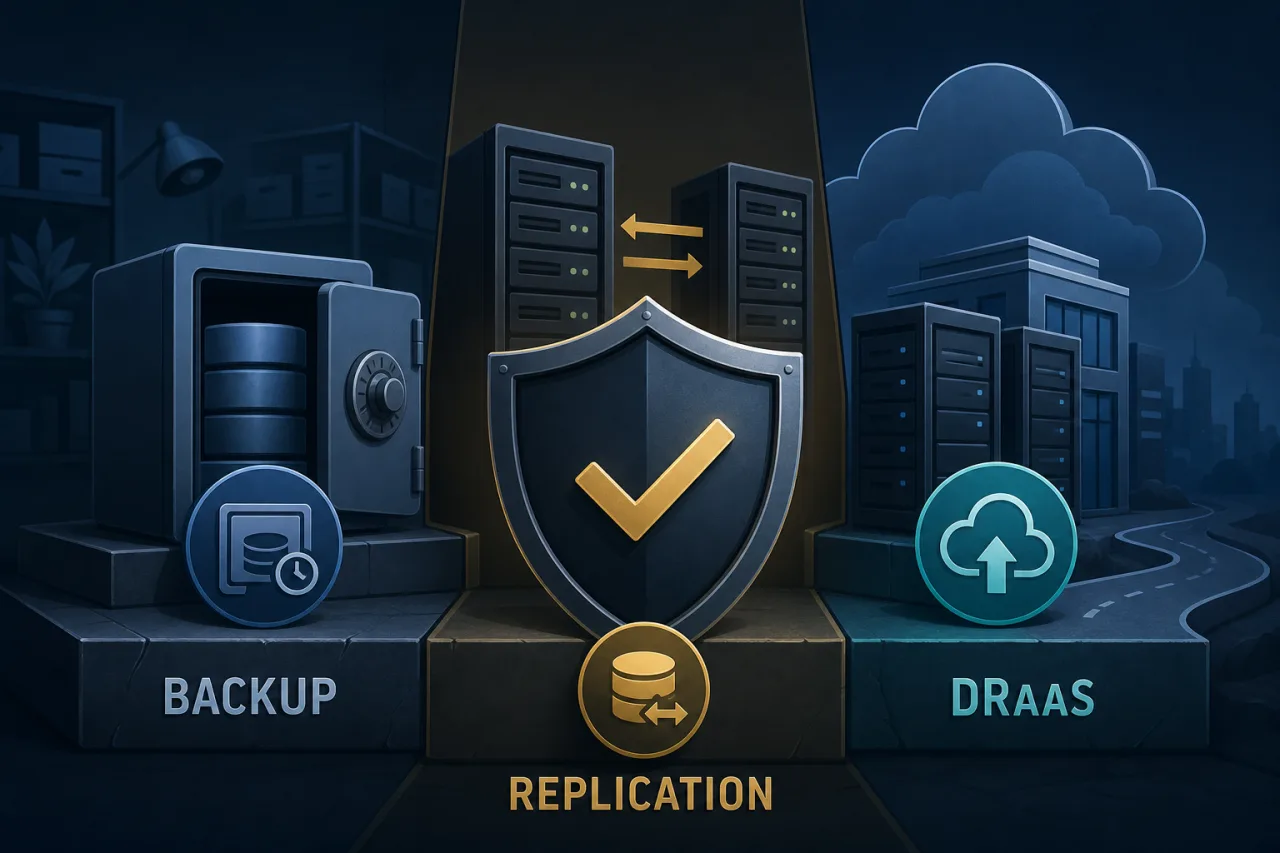
Backup vs Replication vs DRaaS — What Actually Protects You
Three terms that sound interchangeable but solve completely different problems — here's how to tell them apart and know which one you actually need.
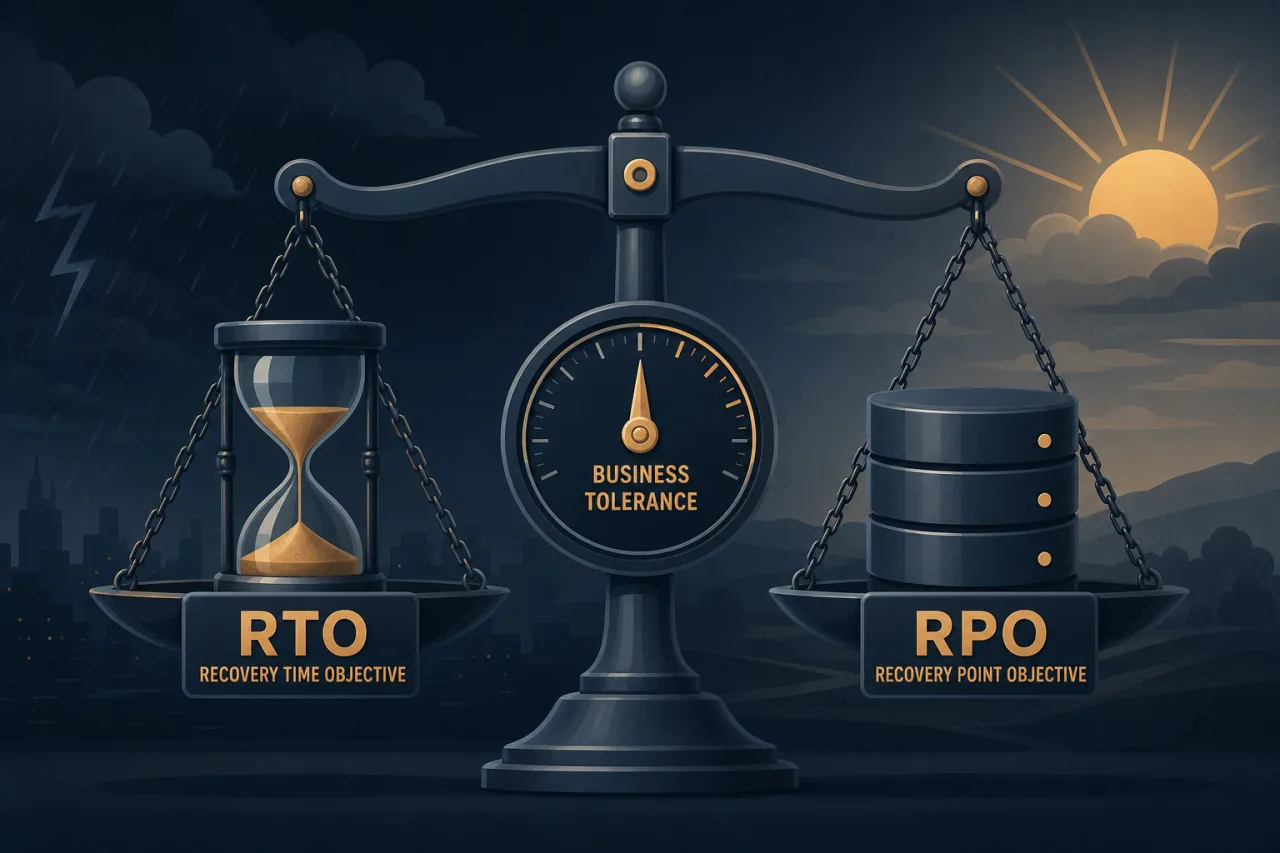
RTO vs RPO: Setting Recovery Targets That Match the Business
A practical guide to defining Recovery Time Objectives and Recovery Point Objectives that reflect what your business can actually tolerate — not just what sounds good in a DR document.
Disaster Recovery as a Service (DRaaS): A Practical Primer
What DRaaS actually is, how it differs from plain backups, and the concrete steps to evaluate and implement it for your infrastructure.
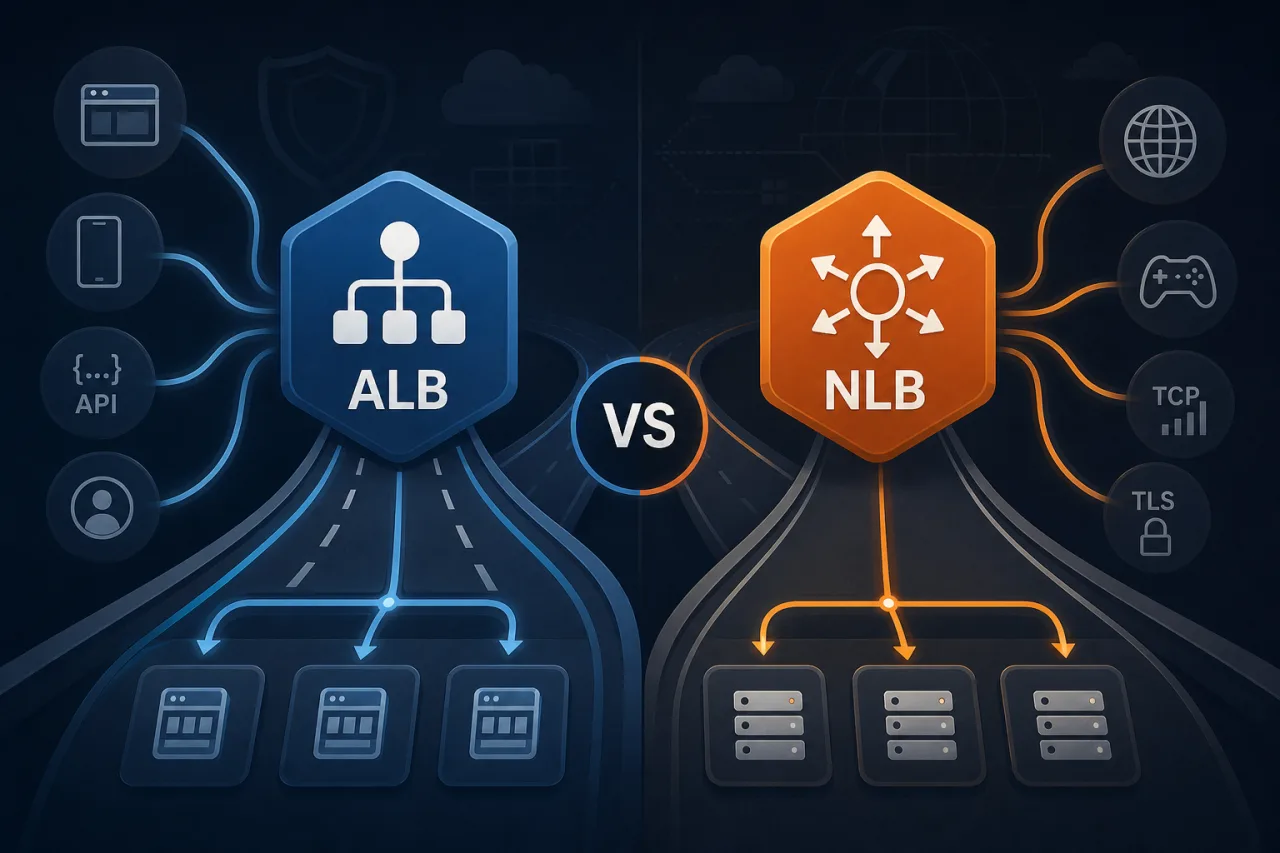
Application Load Balancer vs Network Load Balancer: Choosing Right on AWS
A practical breakdown of when to use ALB versus NLB so you pick the right tool before traffic hits production.