Tutorials
Practical guides on uptime, monitoring, DRaaS, load balancing and AWS reliability from Pingy.io. Tracking an incident? See Outage Reports.
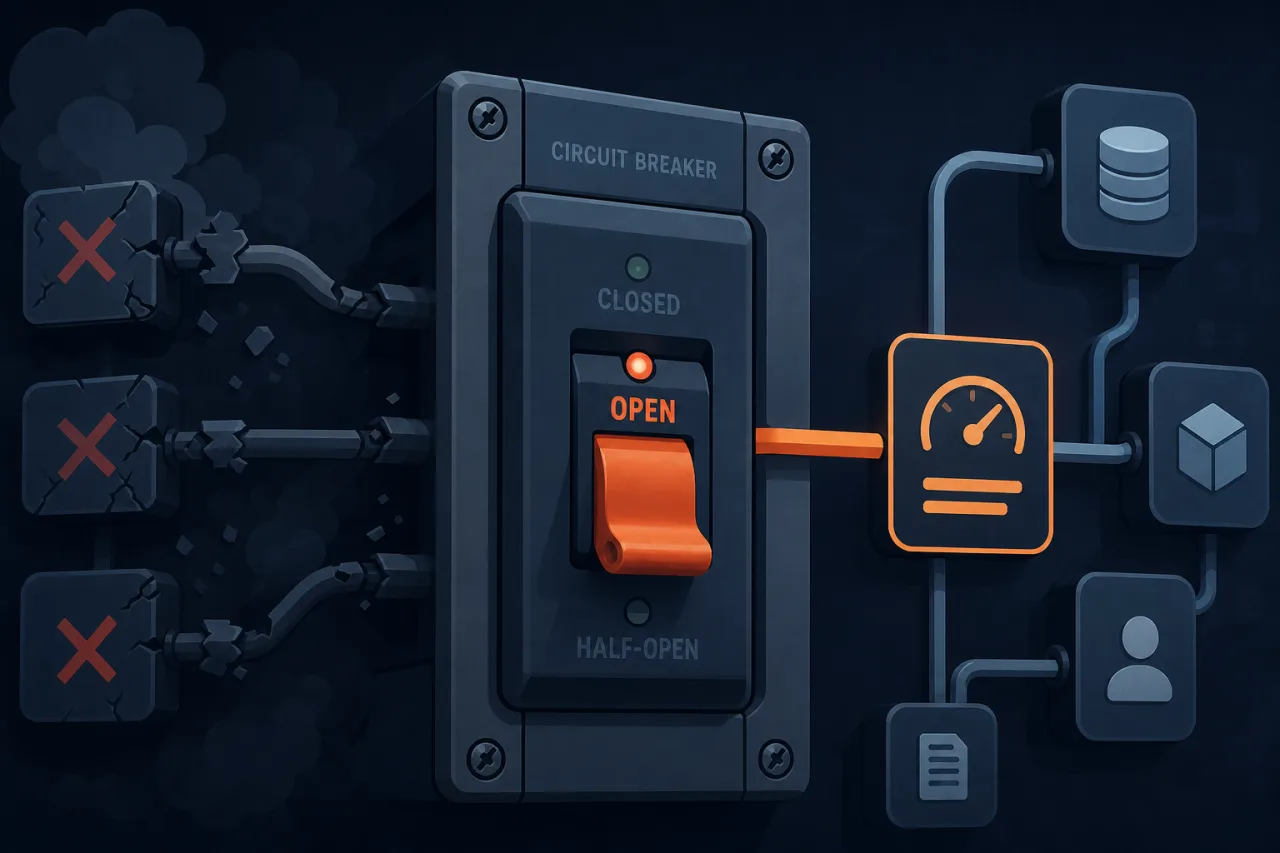
Graceful Degradation and the Circuit Breaker Pattern
Learn how to keep your service partially functional under failure conditions using graceful degradation and the circuit breaker pattern.
Disaster Recovery as a Service (DRaaS): A Practical Primer
What DRaaS actually means, how it differs from backup, and how to evaluate and implement it without getting burned by the fine print.
Status Pages: How to Communicate During an Incident
A practical guide to building and running a status page that keeps users informed and your support queue manageable when things go wrong.
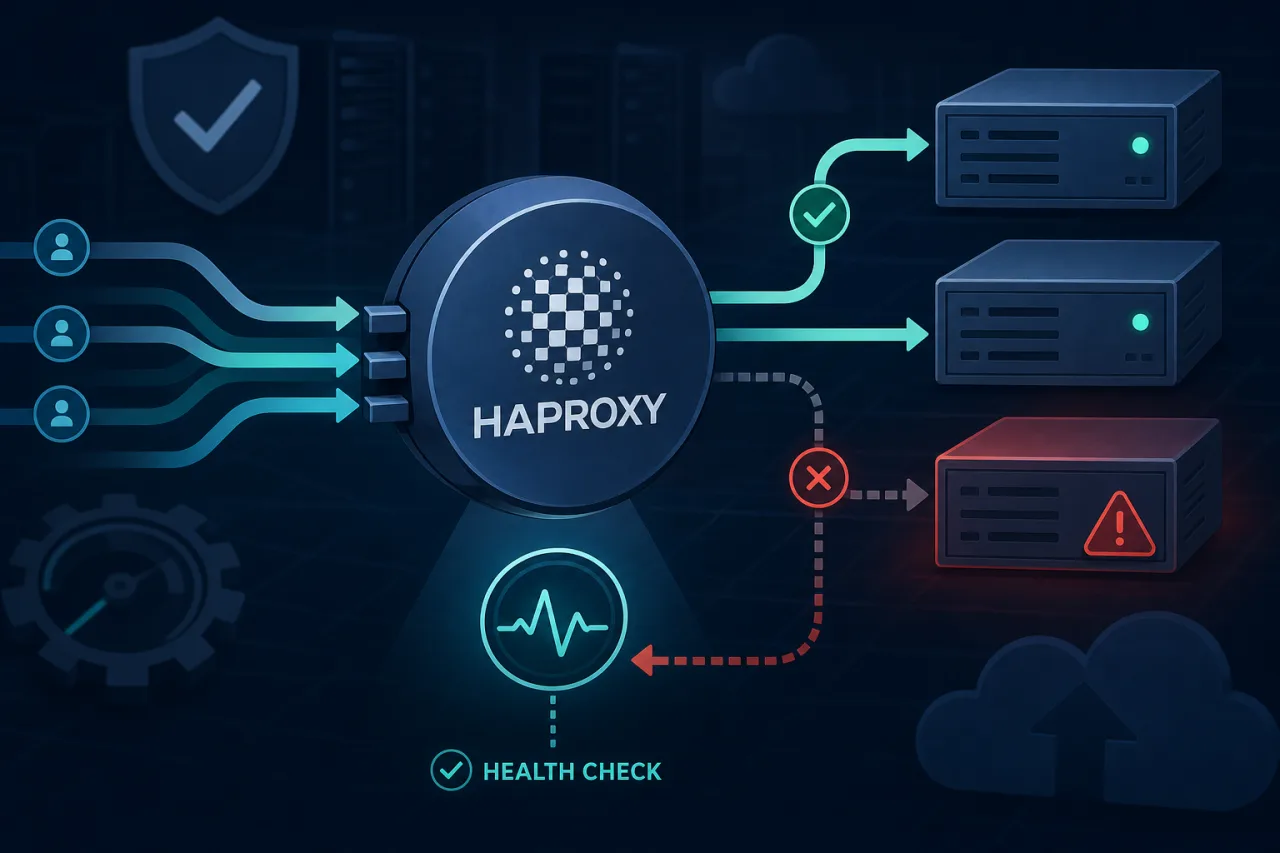
Health-Check-Based Failover with HAProxy
Configure HAProxy's built-in health checks to automatically pull failing backends out of rotation and restore them when they recover.
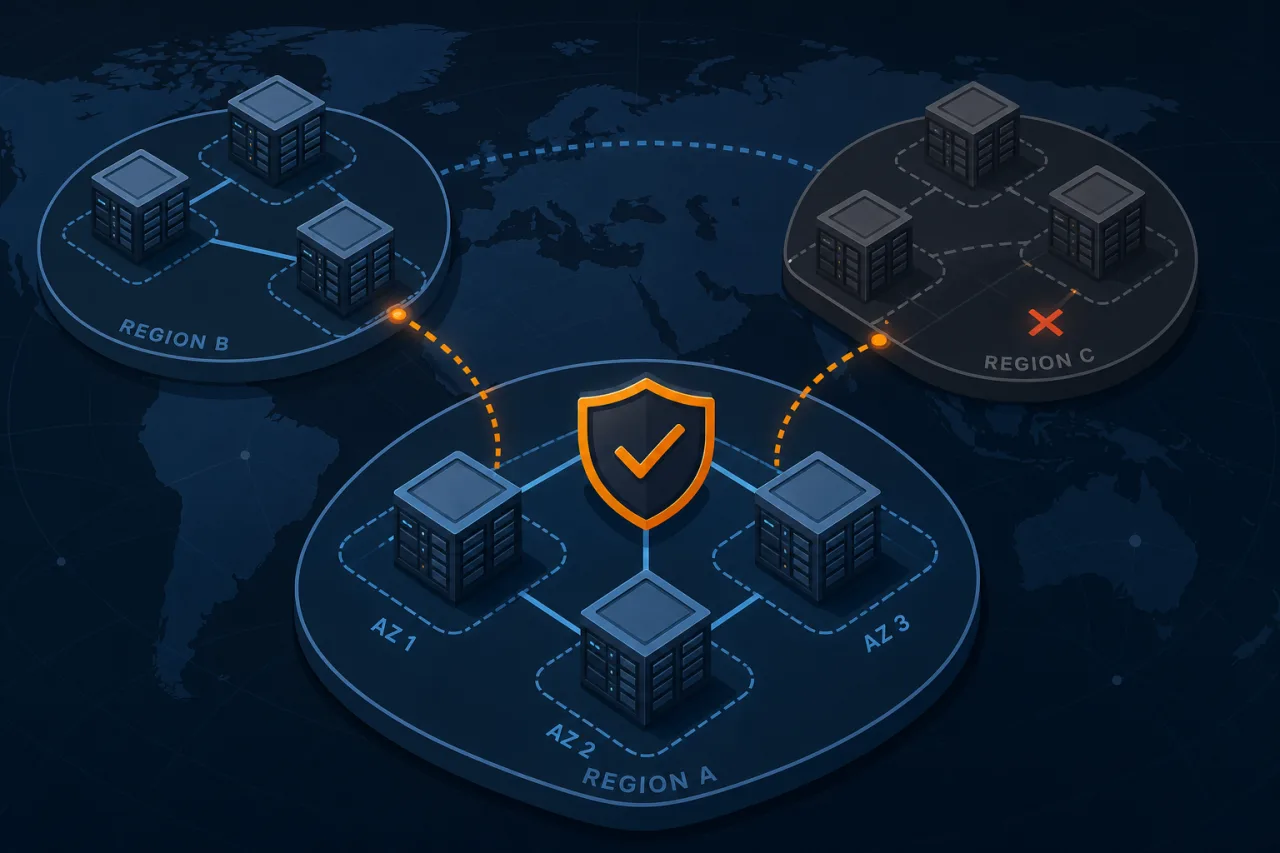
AWS Regions and Availability Zones: How to Architect Across Them
A practical guide to understanding AWS Regions and AZs, and how to design systems that stay up when infrastructure fails.
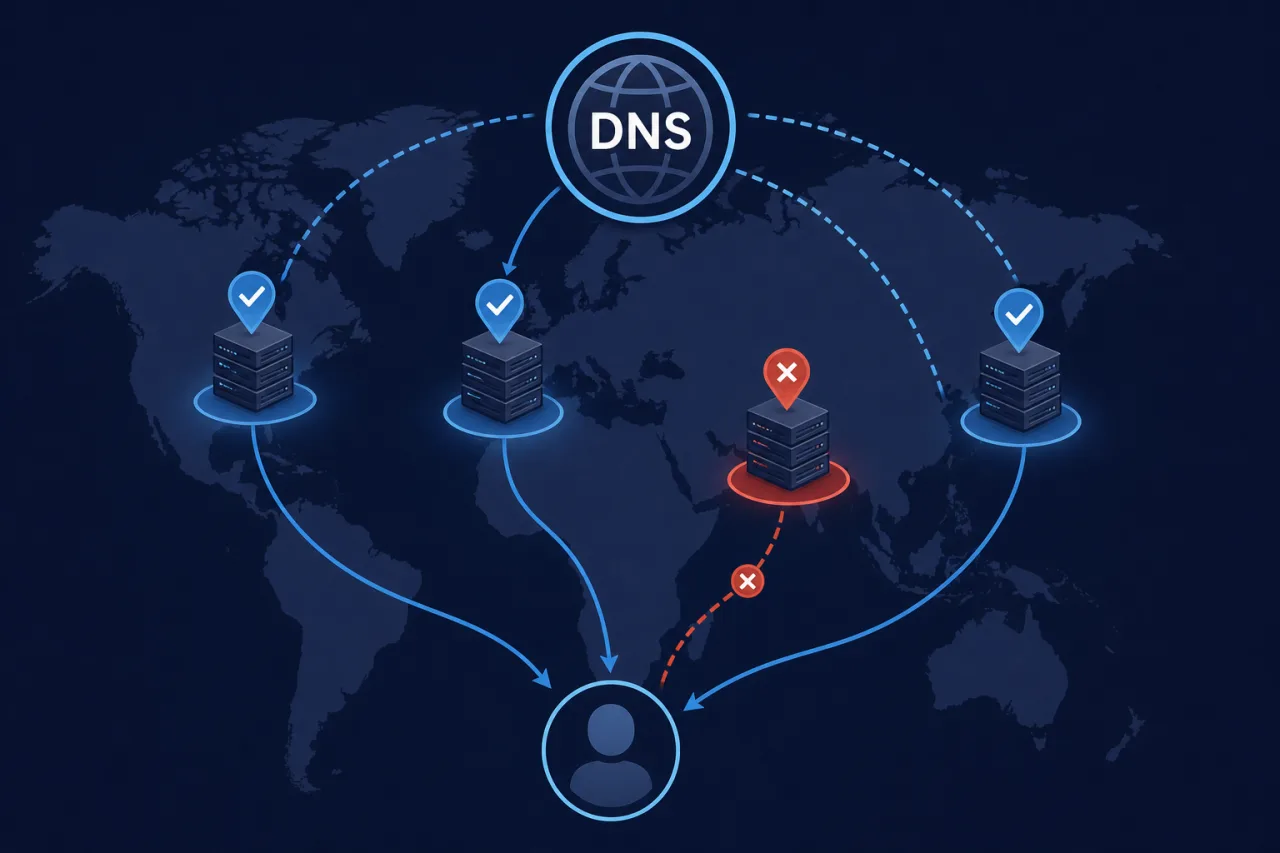
Global Server Load Balancing and Anycast DNS: A Practical Guide
How GSLB and anycast DNS work together to route traffic across regions, reduce latency, and keep services alive when a data center goes down.
Building a Warm-Standby Disaster Recovery Site
A practical walkthrough for engineers who need a secondary site that can take production traffic within minutes, not hours.
Setting Realistic SLOs, SLAs, and Error Budgets
A practical guide to defining service-level objectives that your team can actually hit—and what to do when you don't.
How to Run a Disaster-Recovery Game Day
A step-by-step guide to planning, executing, and learning from a structured DR drill before a real incident forces your hand.
How to Design for Five-Nines (99.999%) Uptime
A practical breakdown of the architecture, processes, and trade-offs required to hit 99.999% availability in production.
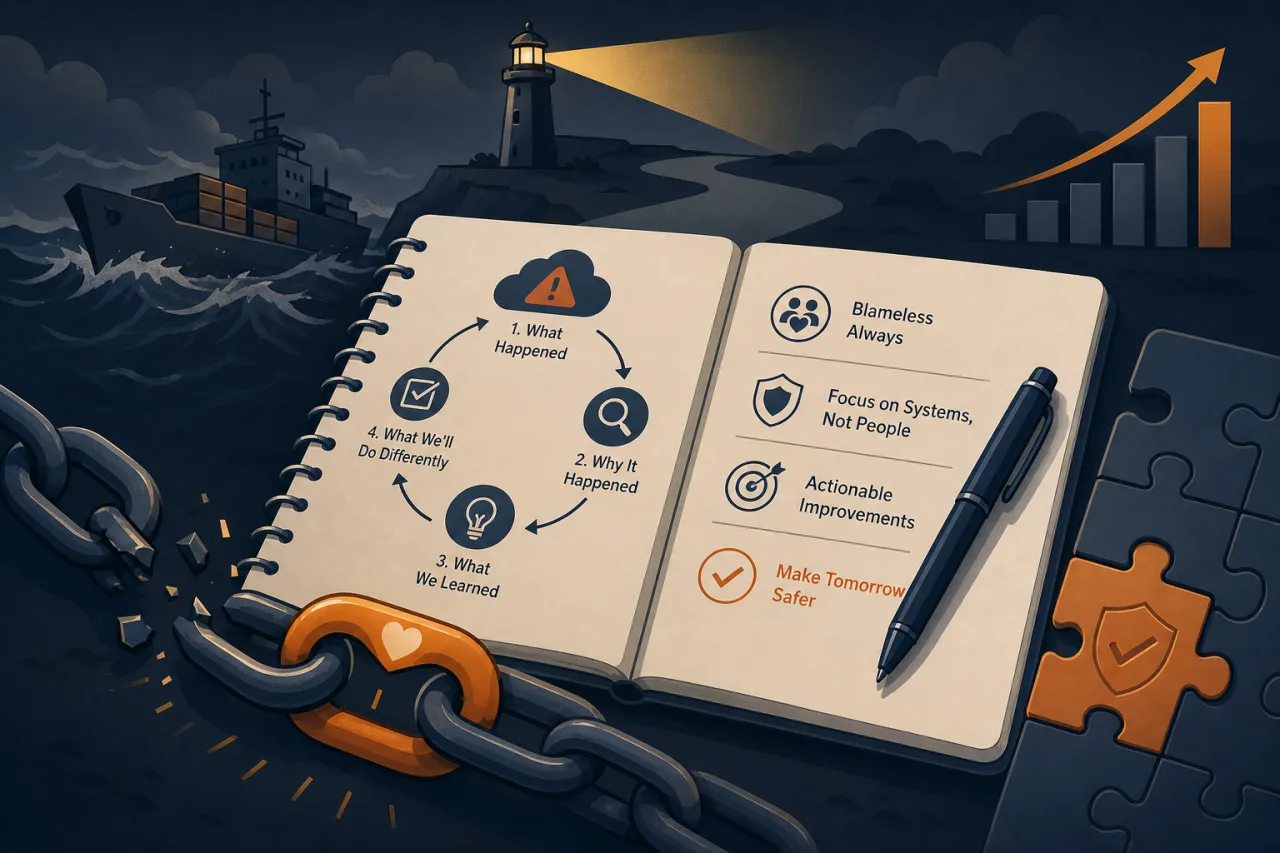
Writing a Blameless Post-Mortem That Actually Helps
A practical guide to turning incident reviews into lasting improvements — without turning them into blame sessions.
BGP Route Leaks: What Fails and How to Investigate
Trace an accidental transit path, understand the limits of origin validation, and collect evidence for a regional reachability problem.