Tutorials
Practical guides on uptime, monitoring, DRaaS, load balancing and AWS reliability from Pingy.io. Tracking an incident? See Outage Reports.
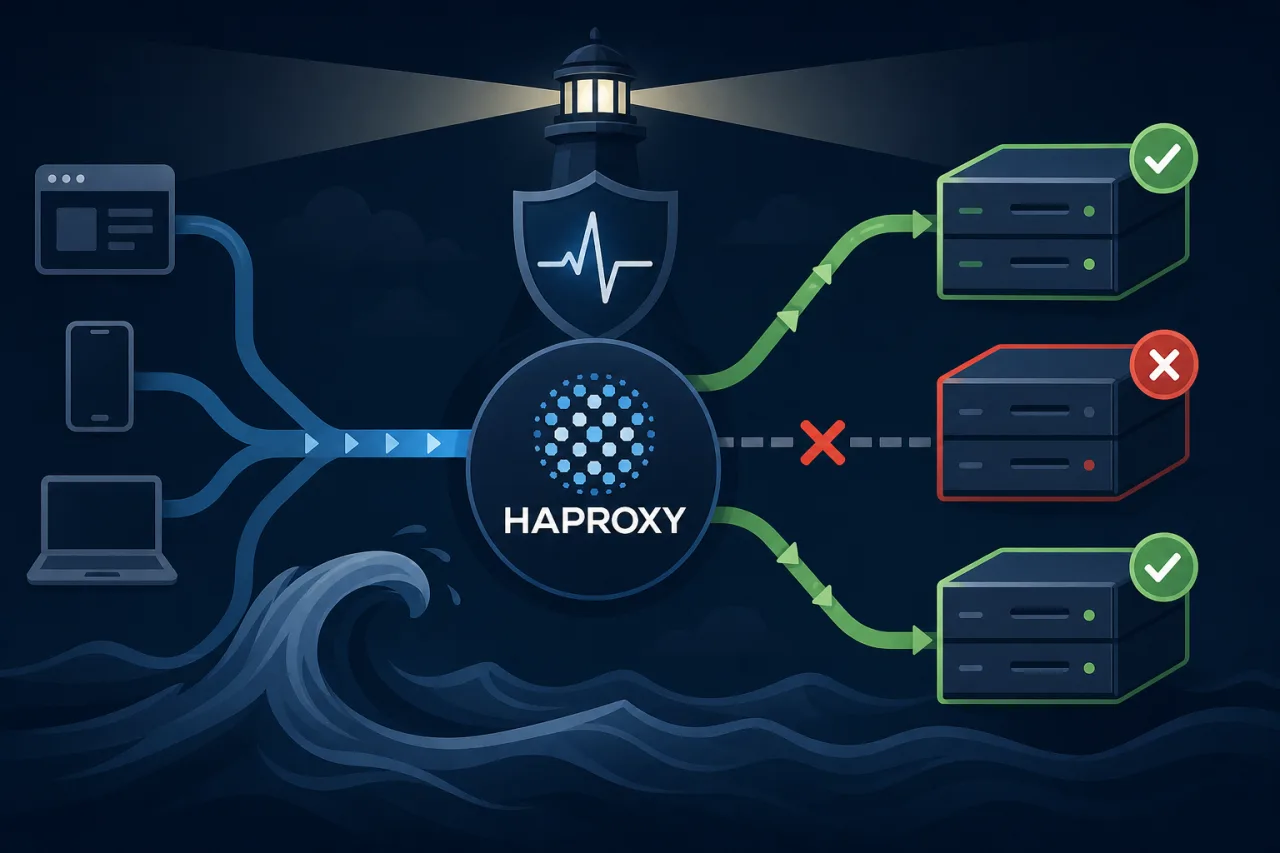
Health-Check-Based Failover with HAProxy
Configure HAProxy's built-in health checks to automatically pull failing backends out of rotation and route traffic to healthy nodes without manual intervention.
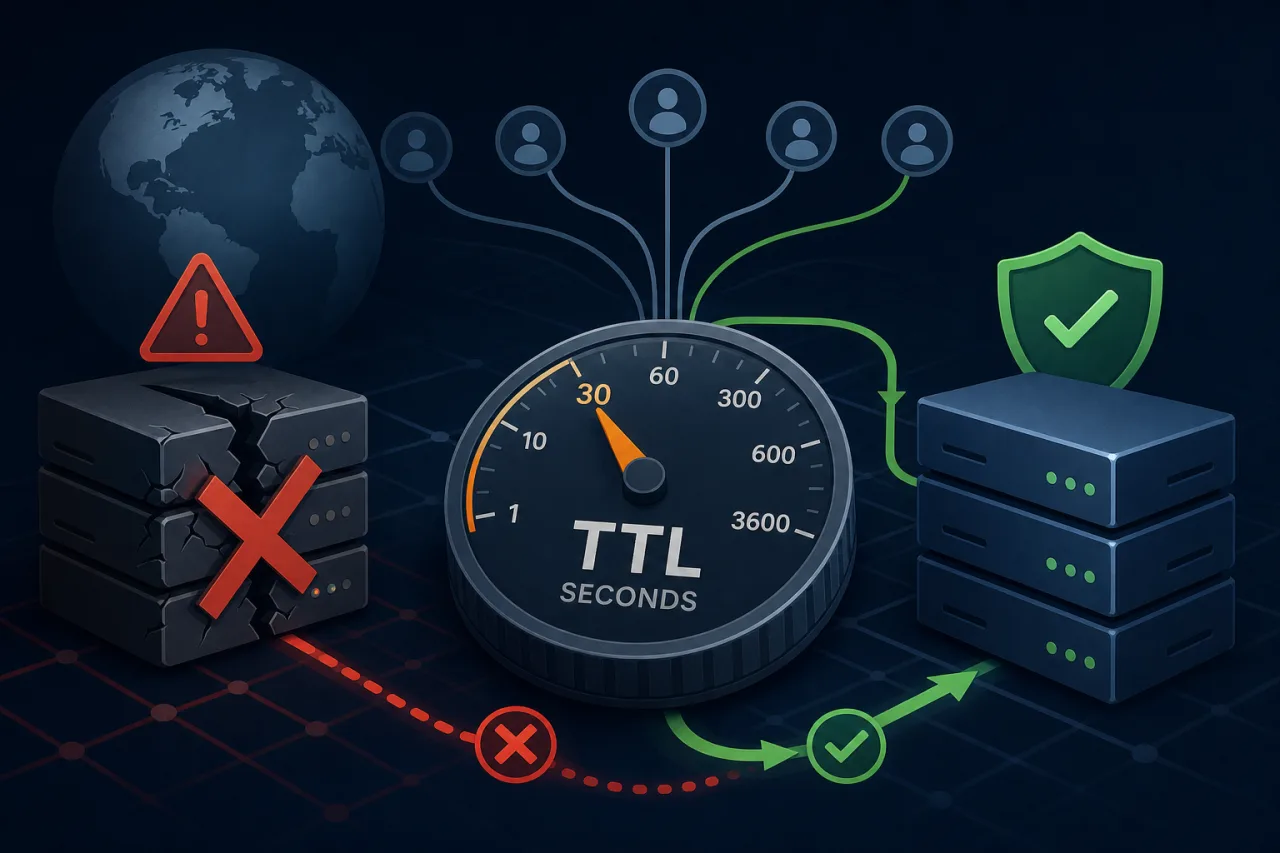
DNS TTLs and Failover: Tuning for Fast Recovery
How to set DNS TTLs strategically so that when something breaks, the internet stops pointing at it as fast as possible.
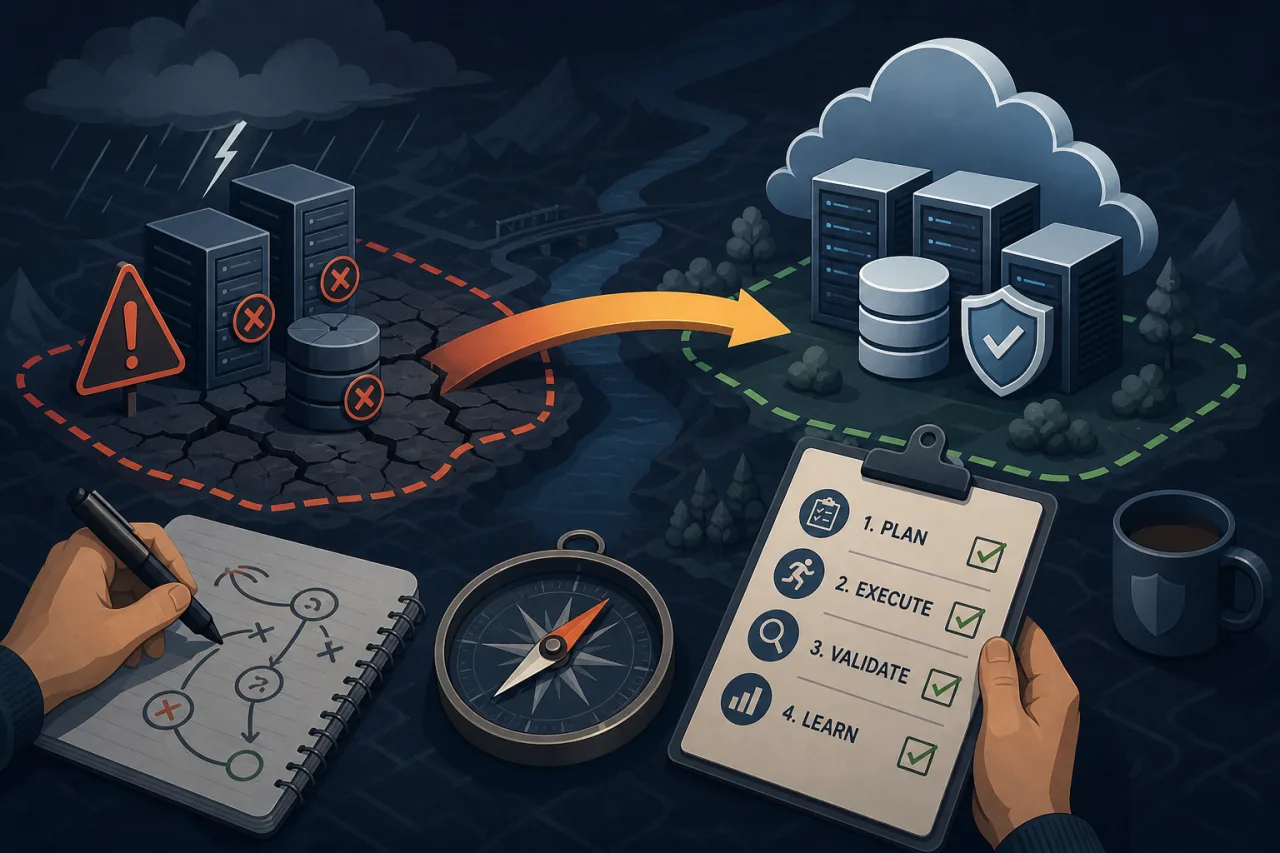
How to Run a Disaster-Recovery Game Day
A step-by-step guide to planning, executing, and learning from a structured DR drill before a real incident forces your hand.
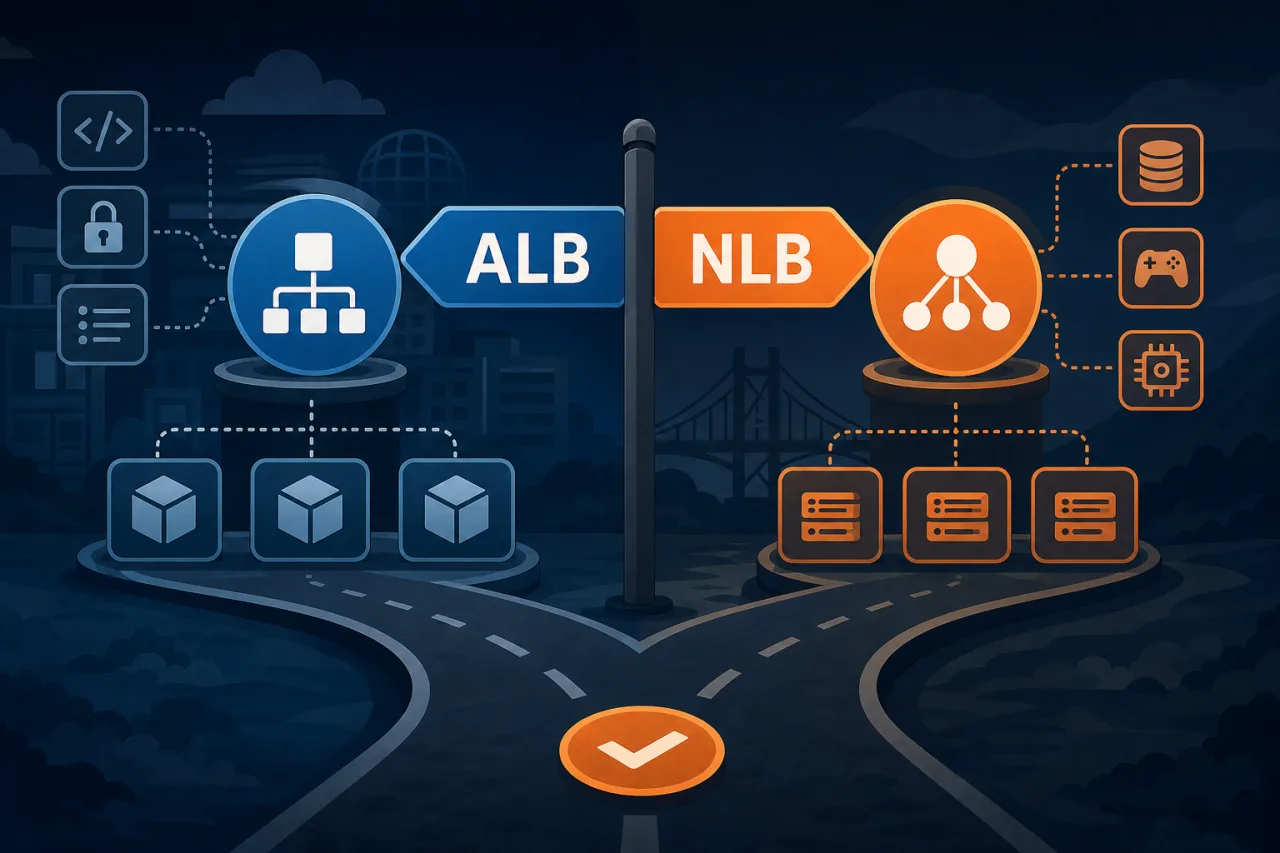
Application Load Balancer vs Network Load Balancer: Choosing the Right One for Your Stack
A practical breakdown of when to use AWS ALB versus NLB, with concrete criteria to help you make the right call before you deploy.
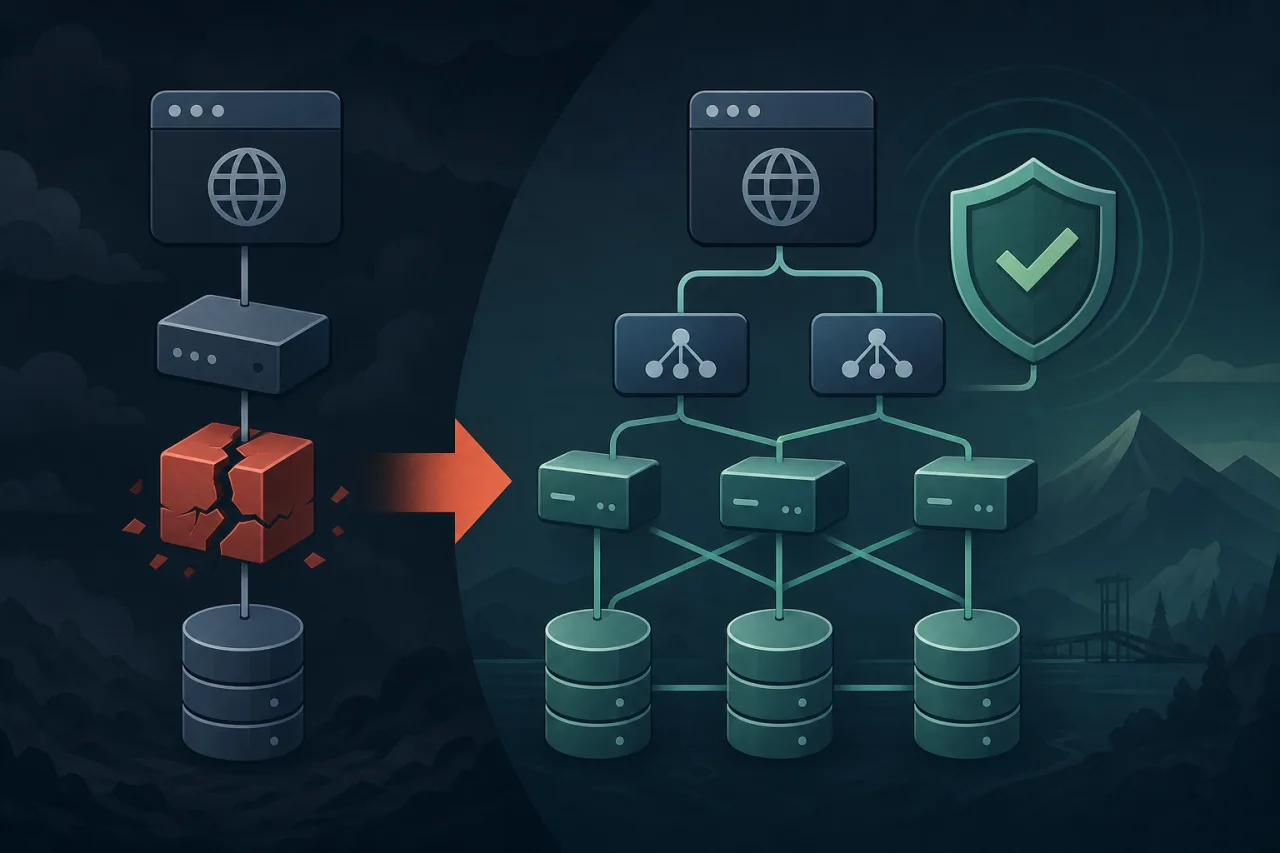
Eliminating Single Points of Failure in Your Web Stack
A practical walkthrough of finding and removing the components whose failure takes your entire service down.
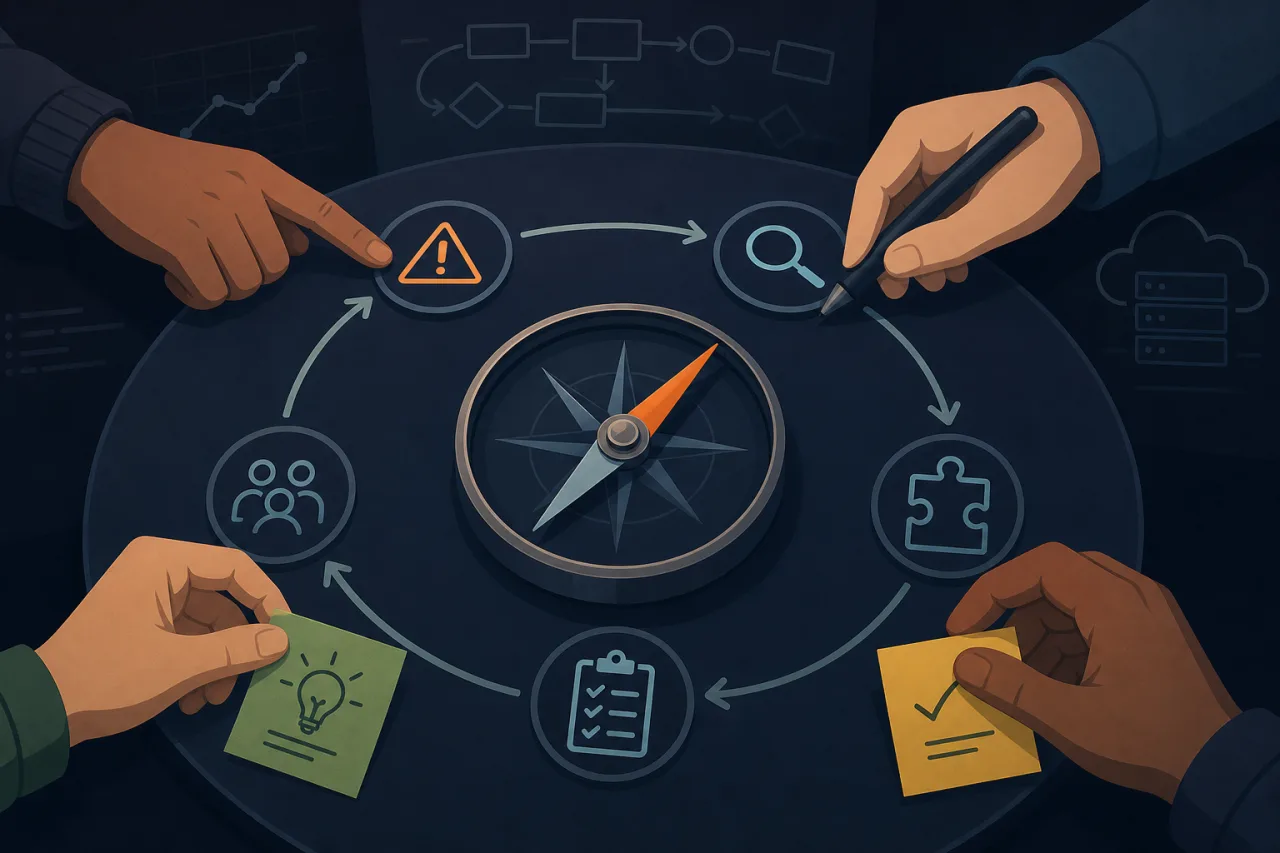
Writing a Blameless Post-Mortem That Actually Helps
A practical guide to turning incident reports into genuine learning—without finger-pointing or empty action items.
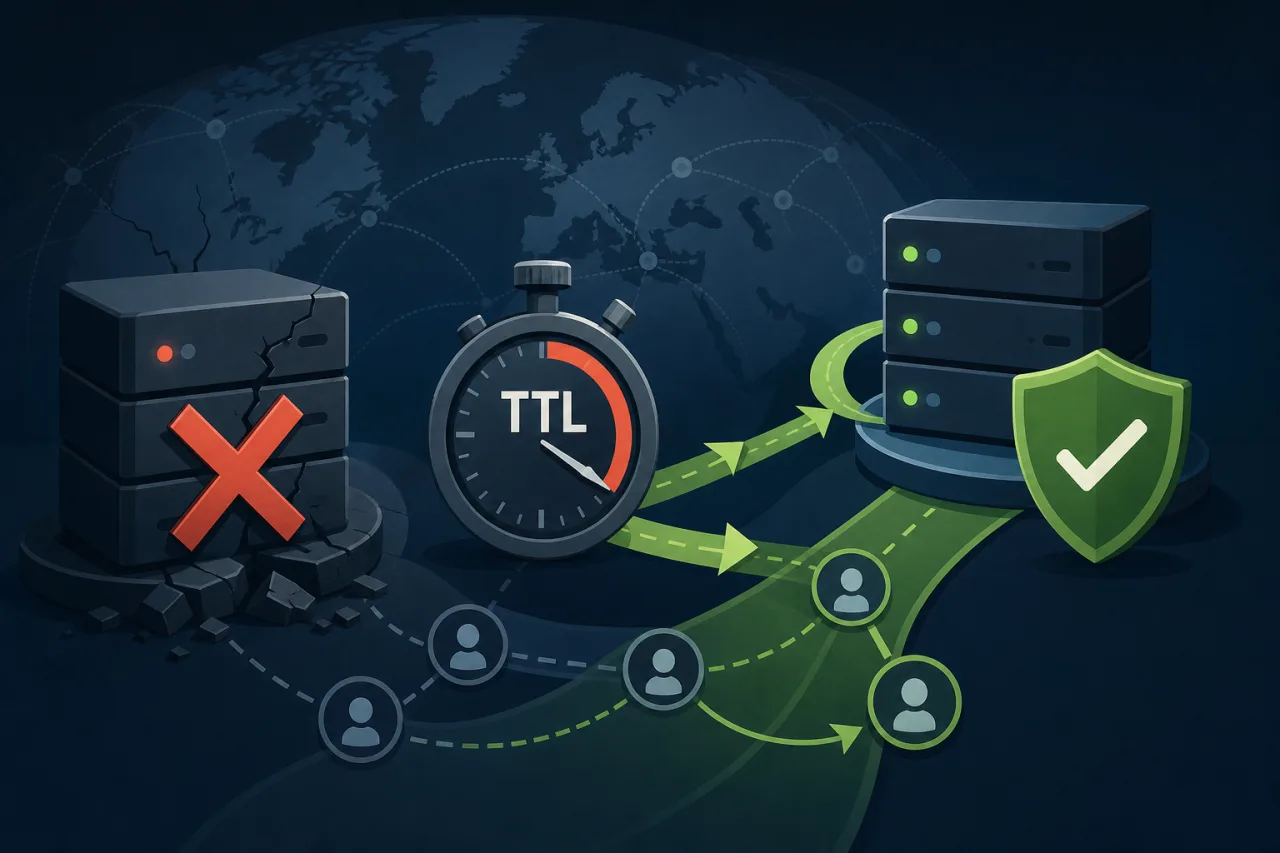
DNS TTLs and Failover: Tuning for Fast Recovery
How to set DNS TTLs strategically so that when something breaks, the internet stops pointing at it as fast as possible.
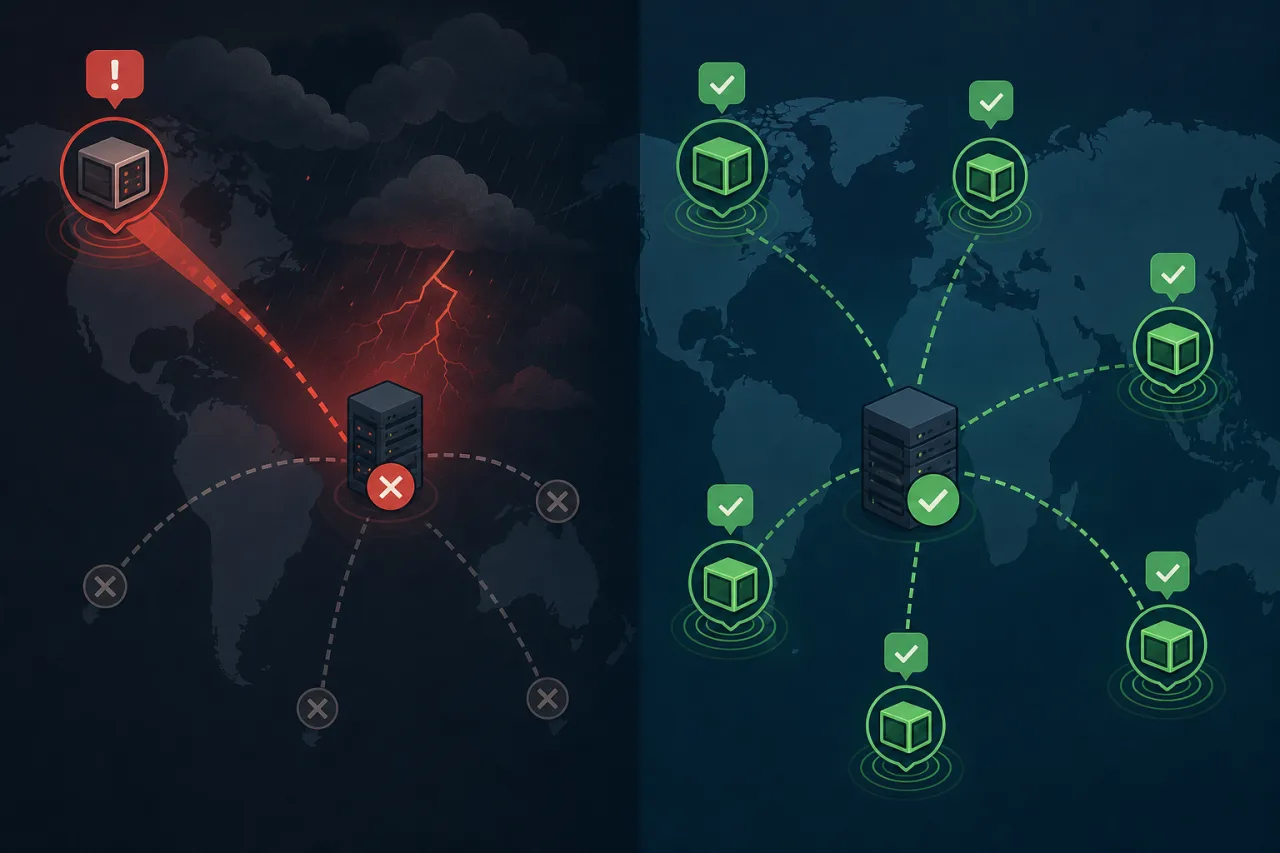
Why Multi-Region Monitoring Beats Single-Location Checks
A single monitoring node can miss real outages and cry wolf on phantom ones — here's why distributing your checks across regions is the right default.
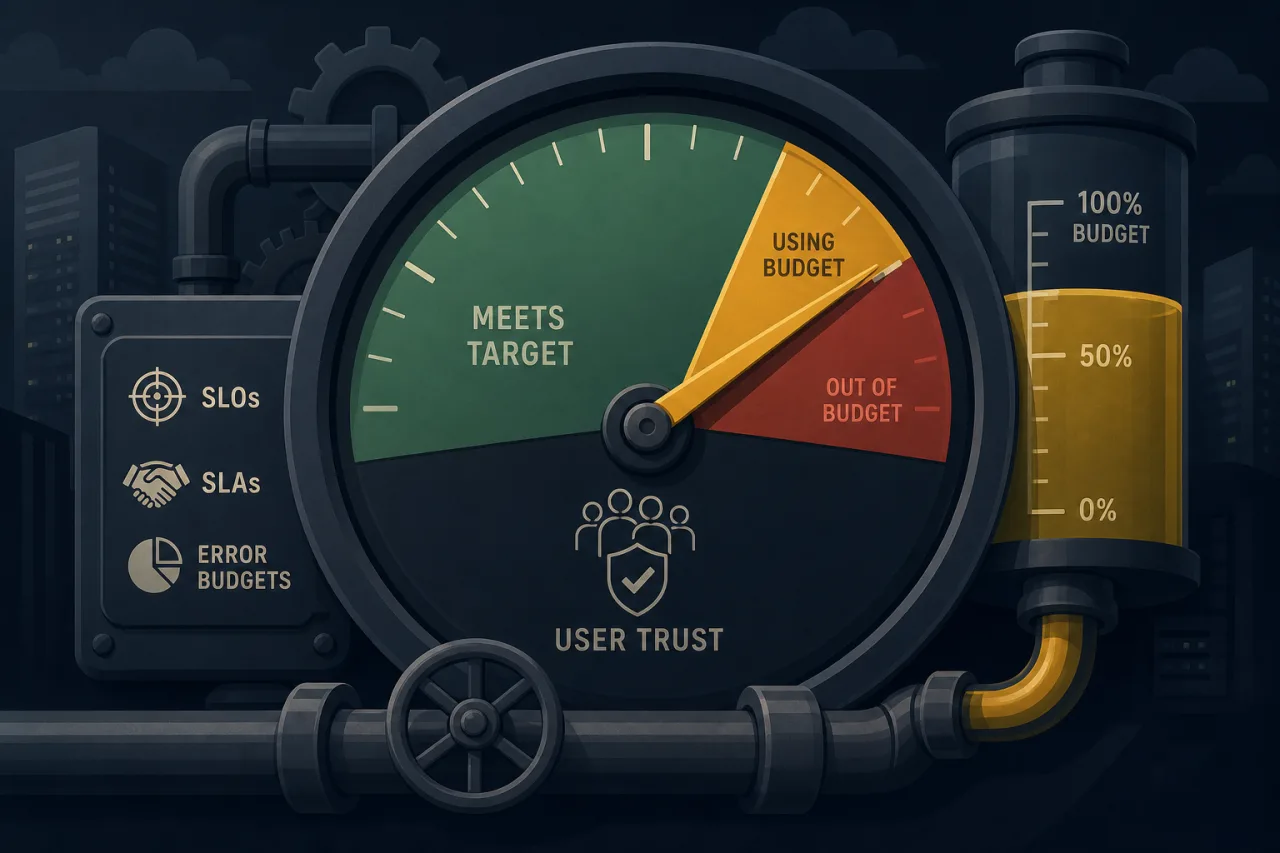
Setting Realistic SLOs, SLAs, and Error Budgets (Without Lying to Yourself)
A practical guide to defining service-level objectives, agreements, and error budgets that your team can actually meet and your users can trust.
Writing a Blameless Post-Mortem That Actually Helps
A practical guide to turning incident write-ups into lasting improvements instead of performative blame-shifting exercises.
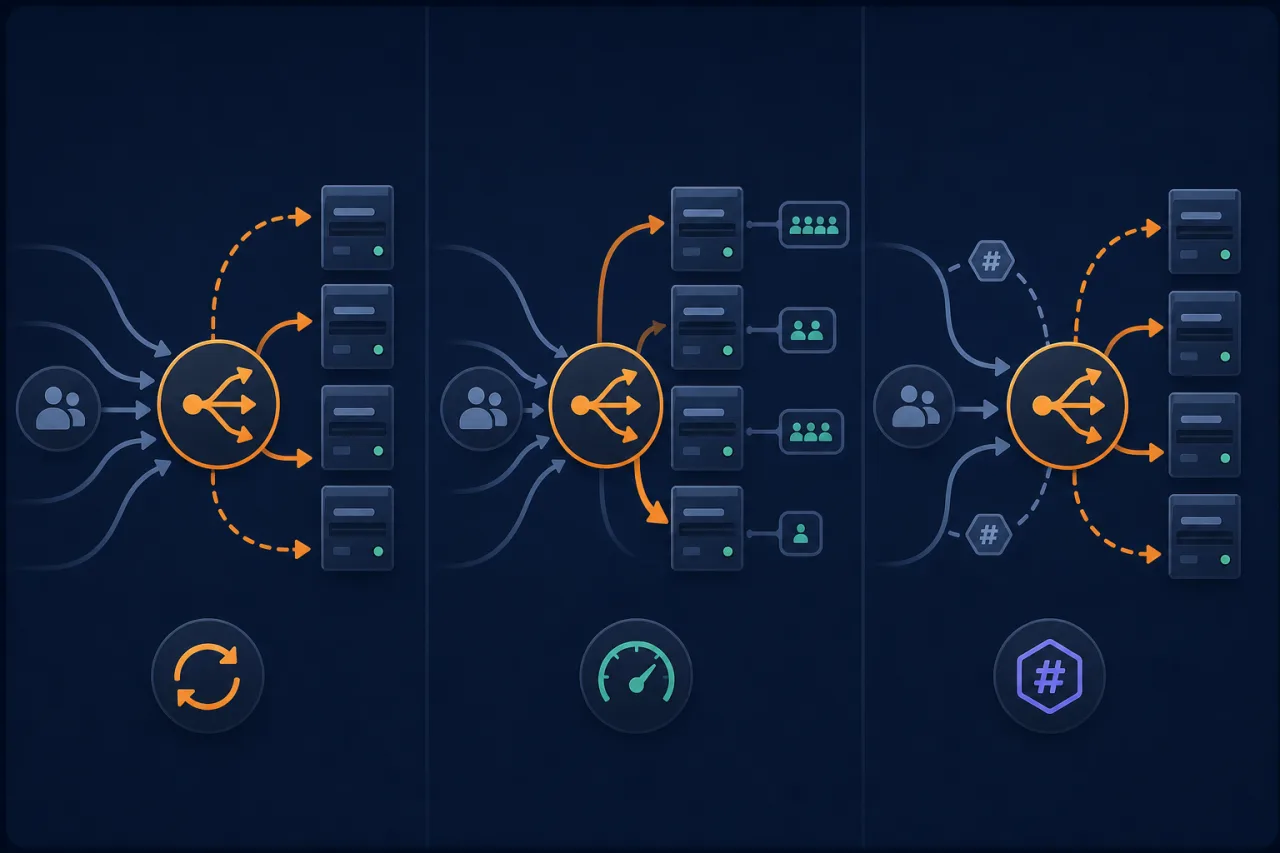
Load Balancing Algorithms Compared: Round-Robin vs Least-Connections vs Hashing
A concrete breakdown of three core load balancing algorithms—how each works, where each wins, and how to choose the right one for your architecture.
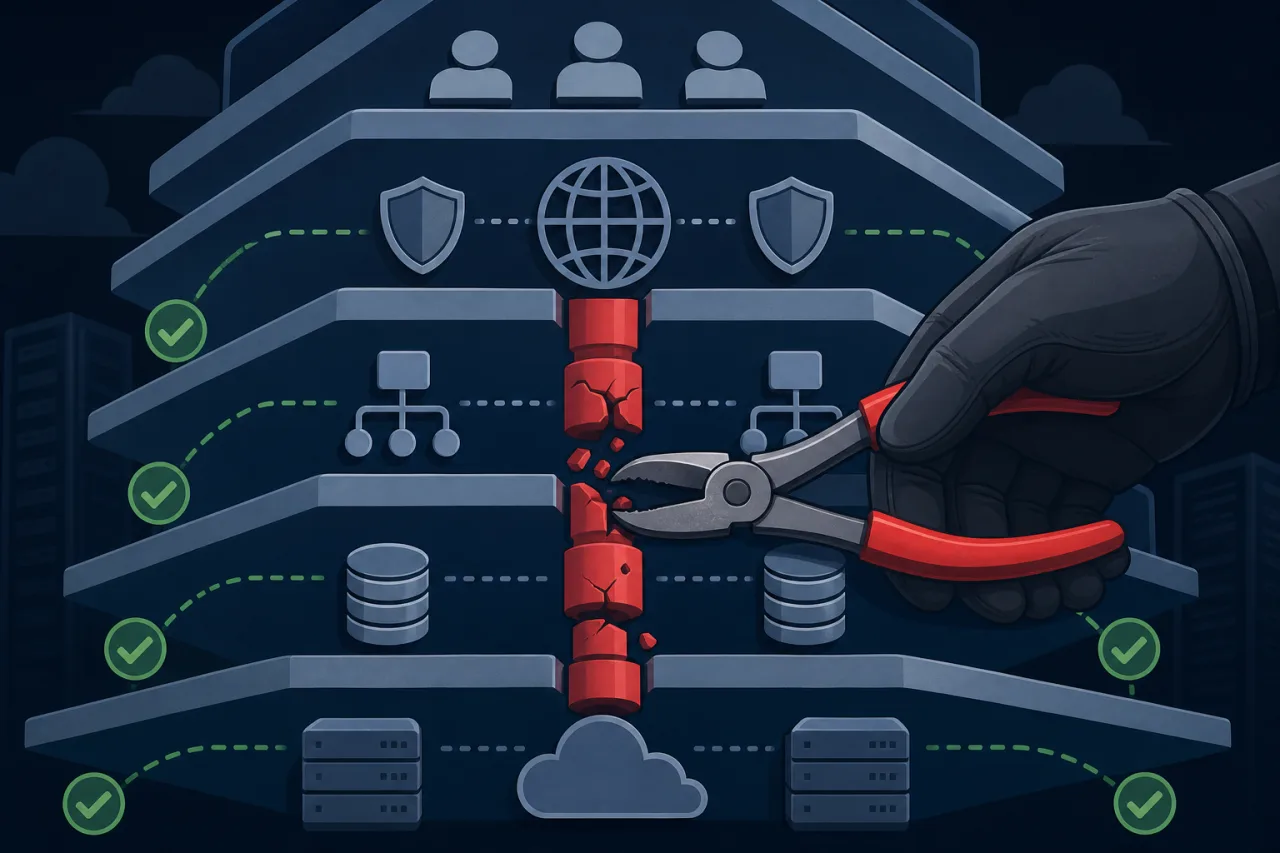
Eliminating Single Points of Failure in Your Web Stack
A practical, layer-by-layer guide to identifying and removing the components whose failure would take your entire service offline.