Tutorials
Practical guides on uptime, monitoring, DRaaS, load balancing and AWS reliability from Pingy.io. Tracking an incident? See Outage Reports.
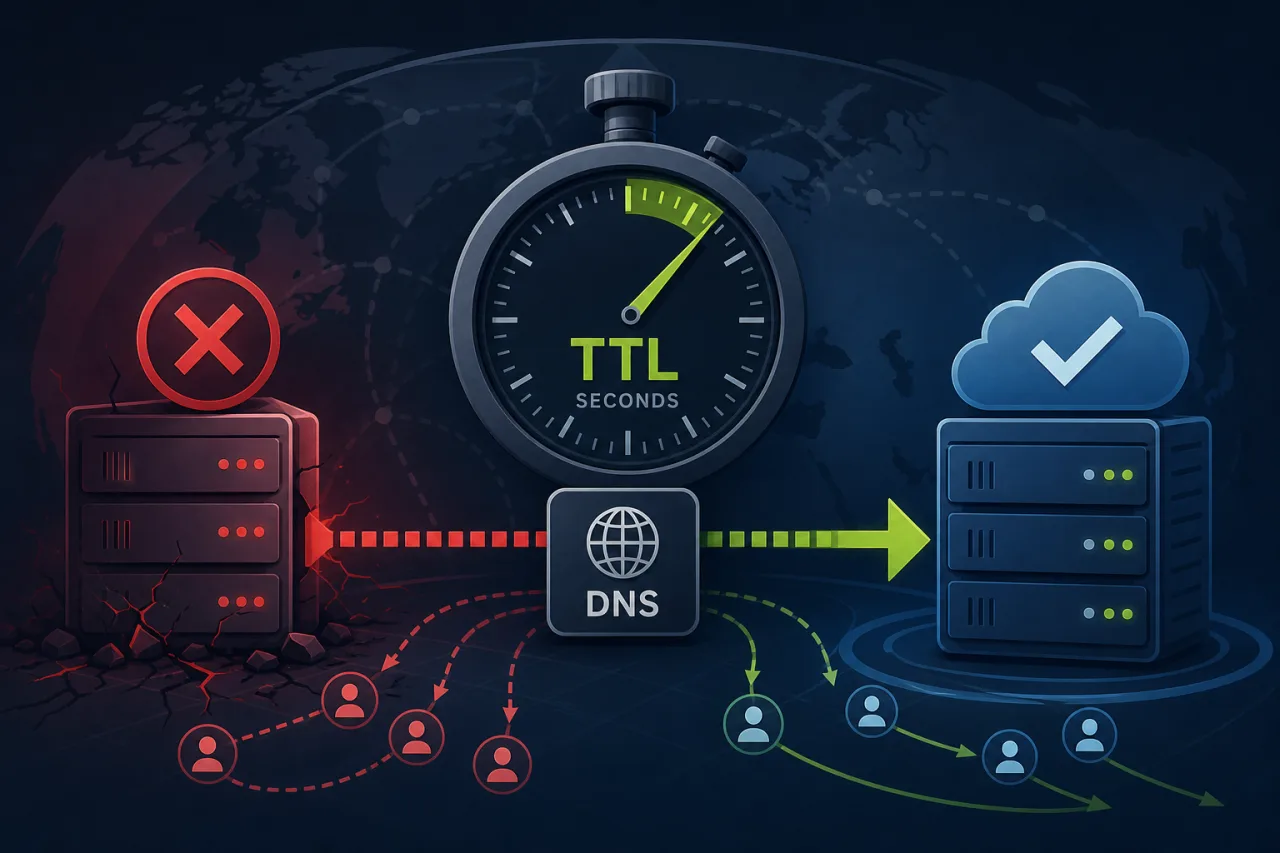
DNS TTLs and Failover: Tuning for Fast Recovery
How to set DNS TTLs strategically so that when something breaks, traffic reroutes in seconds rather than hours.
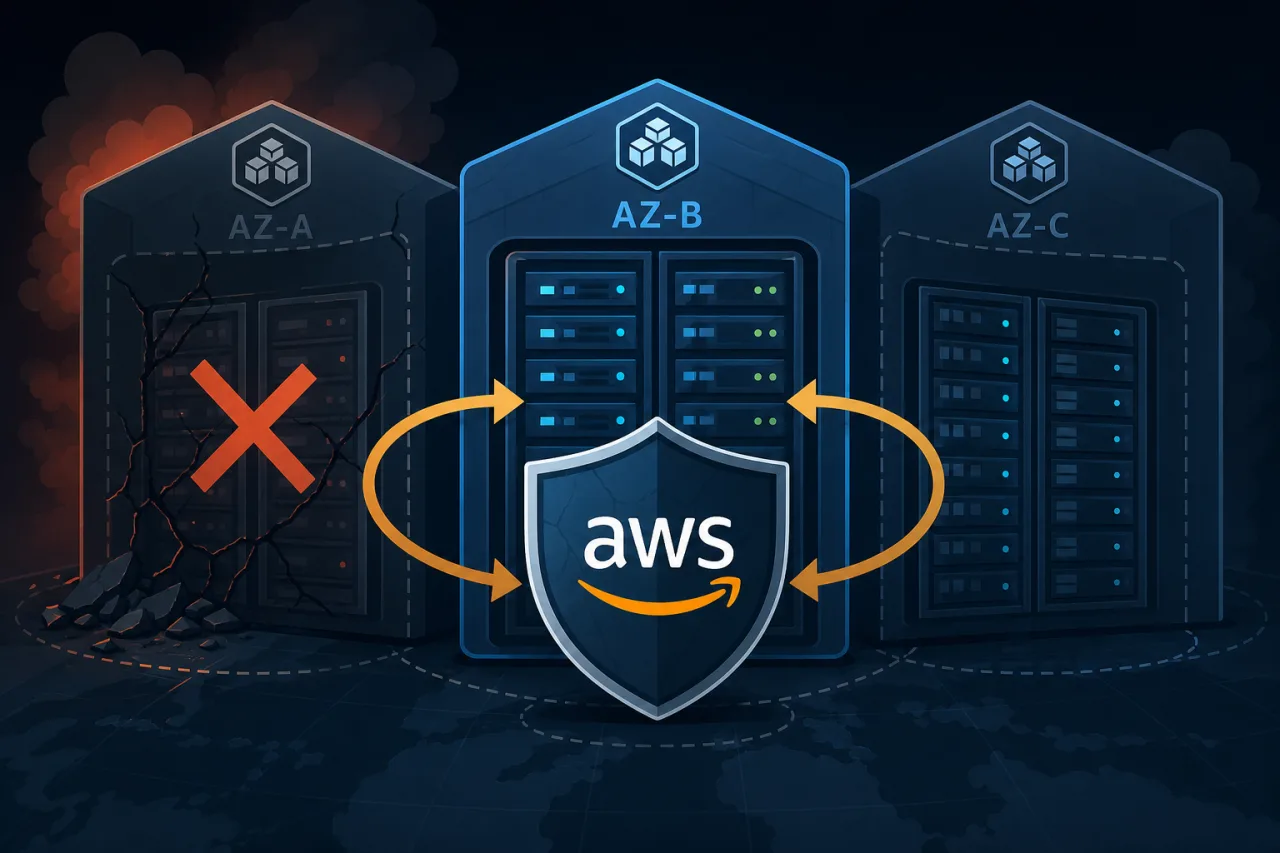
Surviving an AWS AZ Failure with Multi-AZ Design
A practical guide to architecting your AWS workloads so a single Availability Zone outage becomes a non-event instead of an incident.
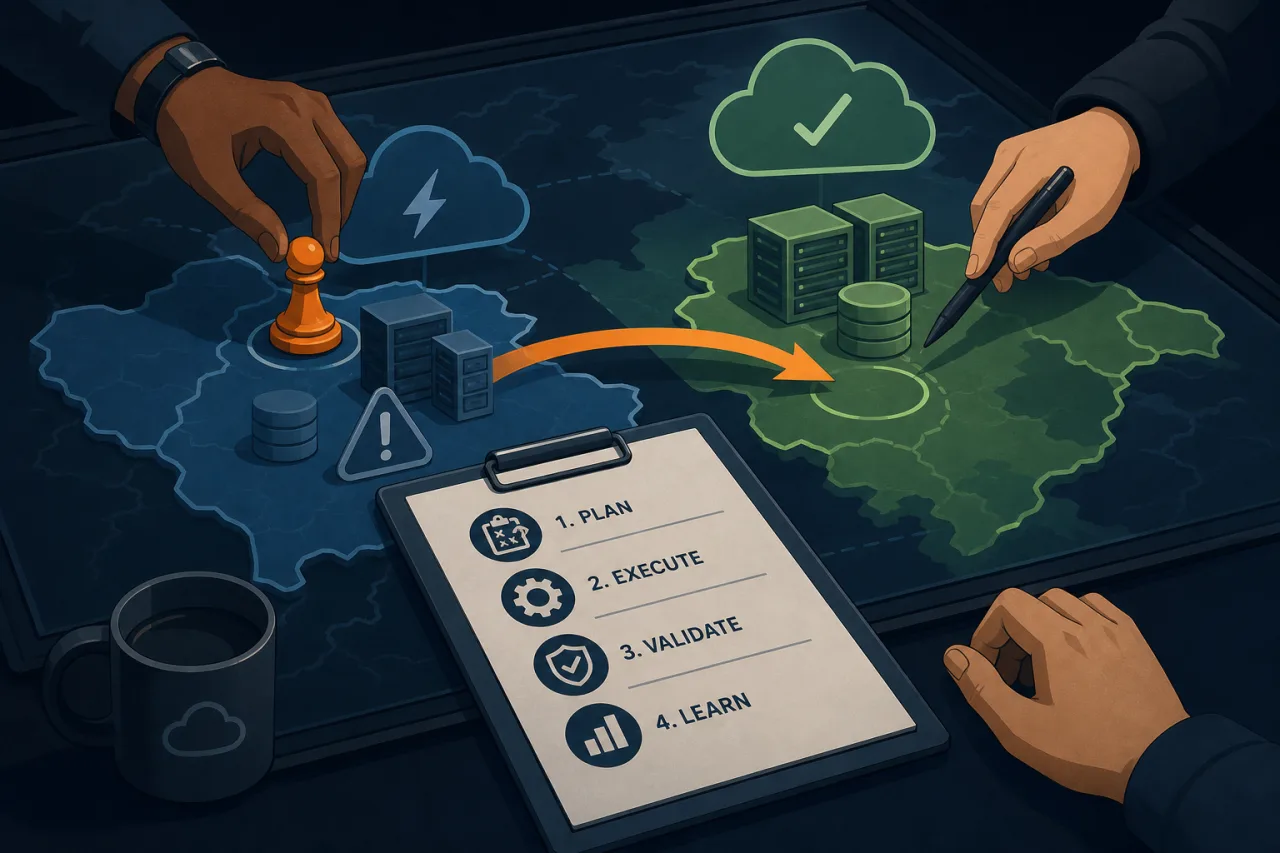
How to Run a Disaster-Recovery Game Day
A step-by-step guide to planning, executing, and learning from a structured DR exercise before a real outage forces your hand.
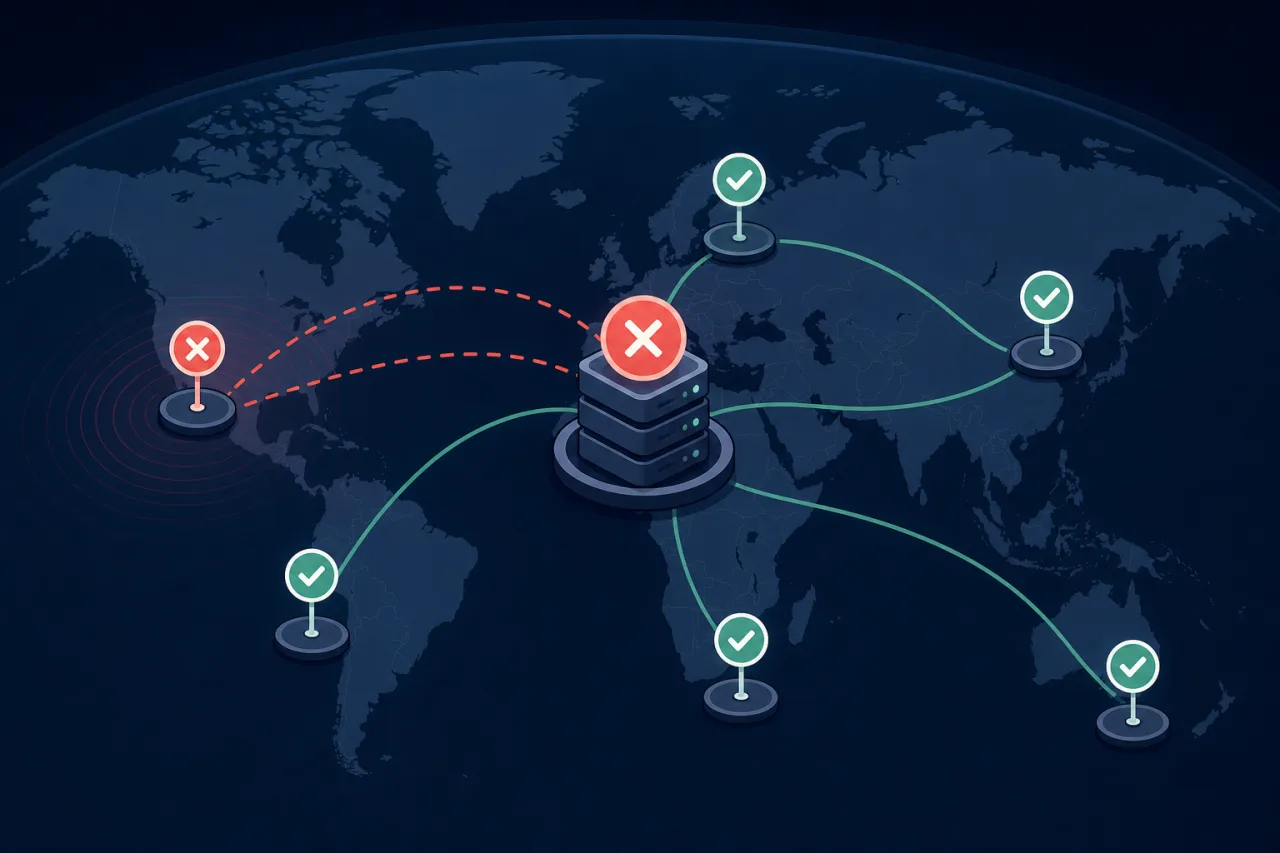
Why Multi-Region Monitoring Beats Single-Location Checks
A single monitoring node can't tell you whether your site is down or just unreachable from one corner of the internet — here's why geography matters for uptime checks.
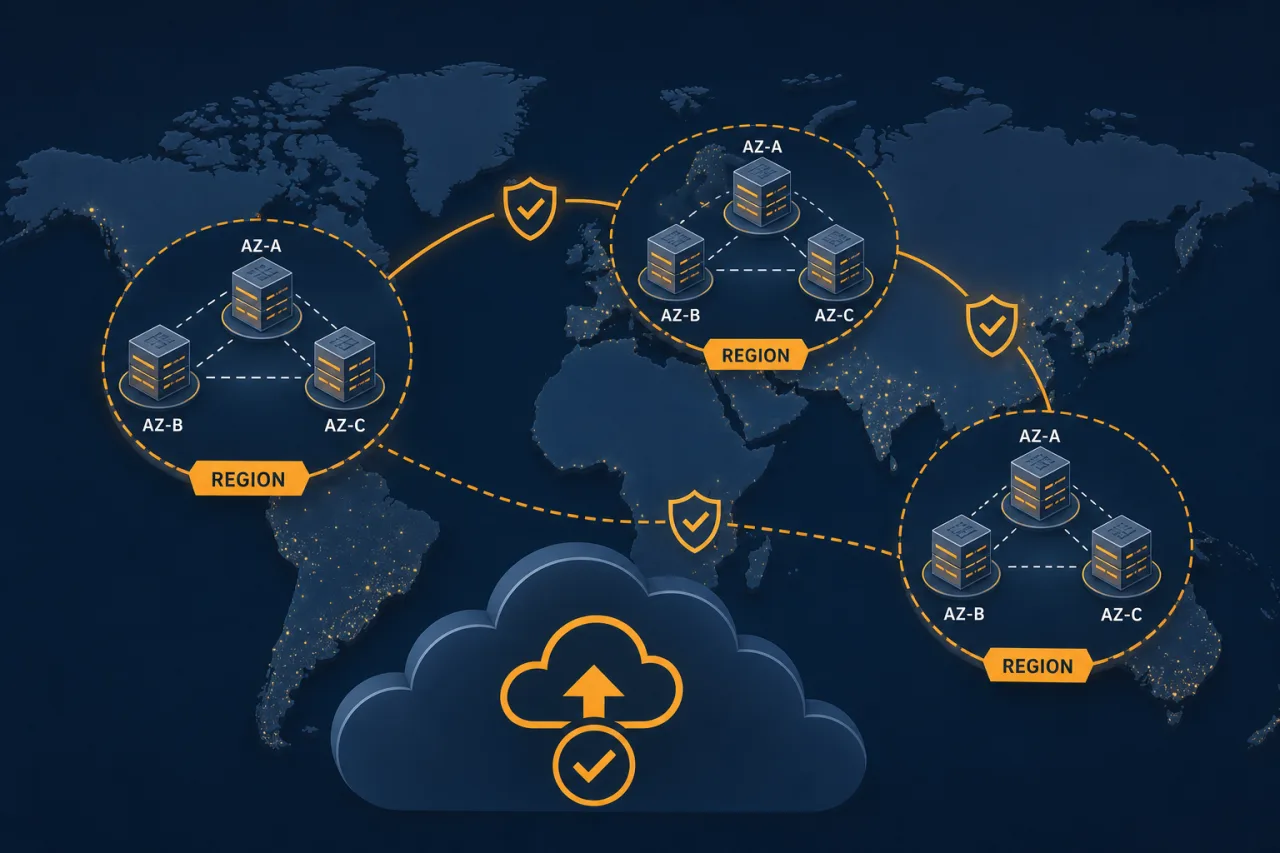
AWS Regions and Availability Zones: How to Architect Across Them
A practical guide to understanding AWS's geographic infrastructure and designing systems that survive zone and region failures.
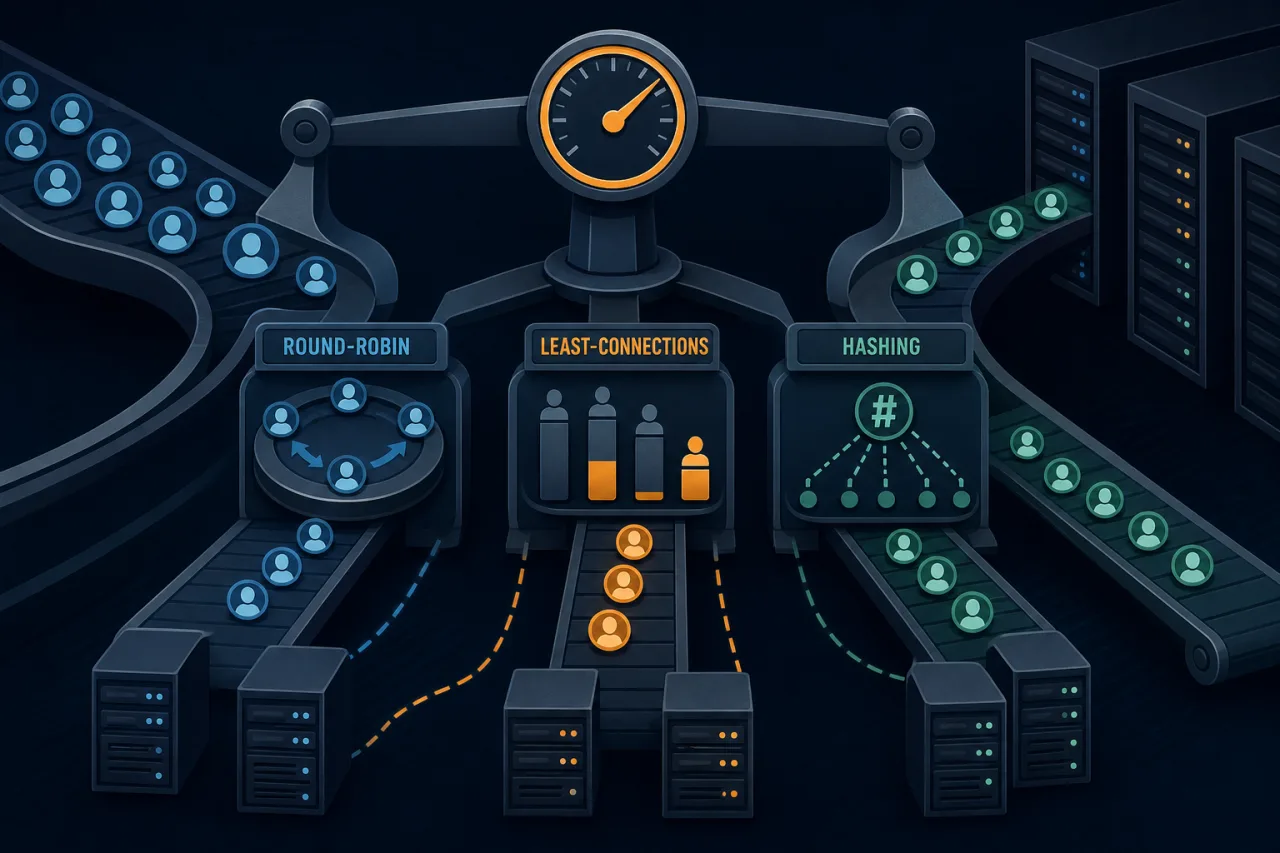
Load Balancing Algorithms Compared: Round-Robin vs Least-Connections vs Hashing
A practical breakdown of how round-robin, least-connections, and hashing algorithms work, when each one shines, and what breaks when you pick the wrong one.
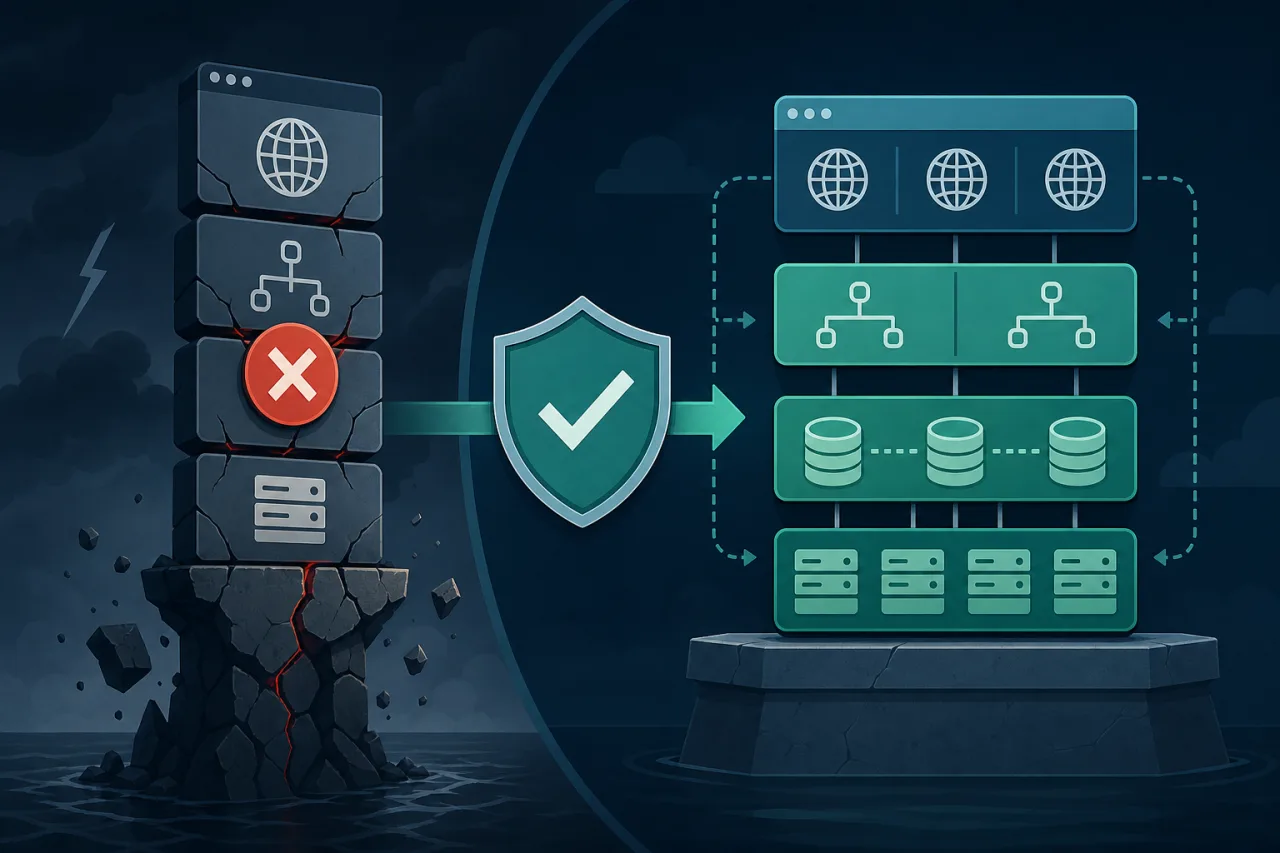
Eliminating Single Points of Failure in Your Web Stack
A practical walkthrough of where SPOFs hide in typical web architectures and how to engineer them out.
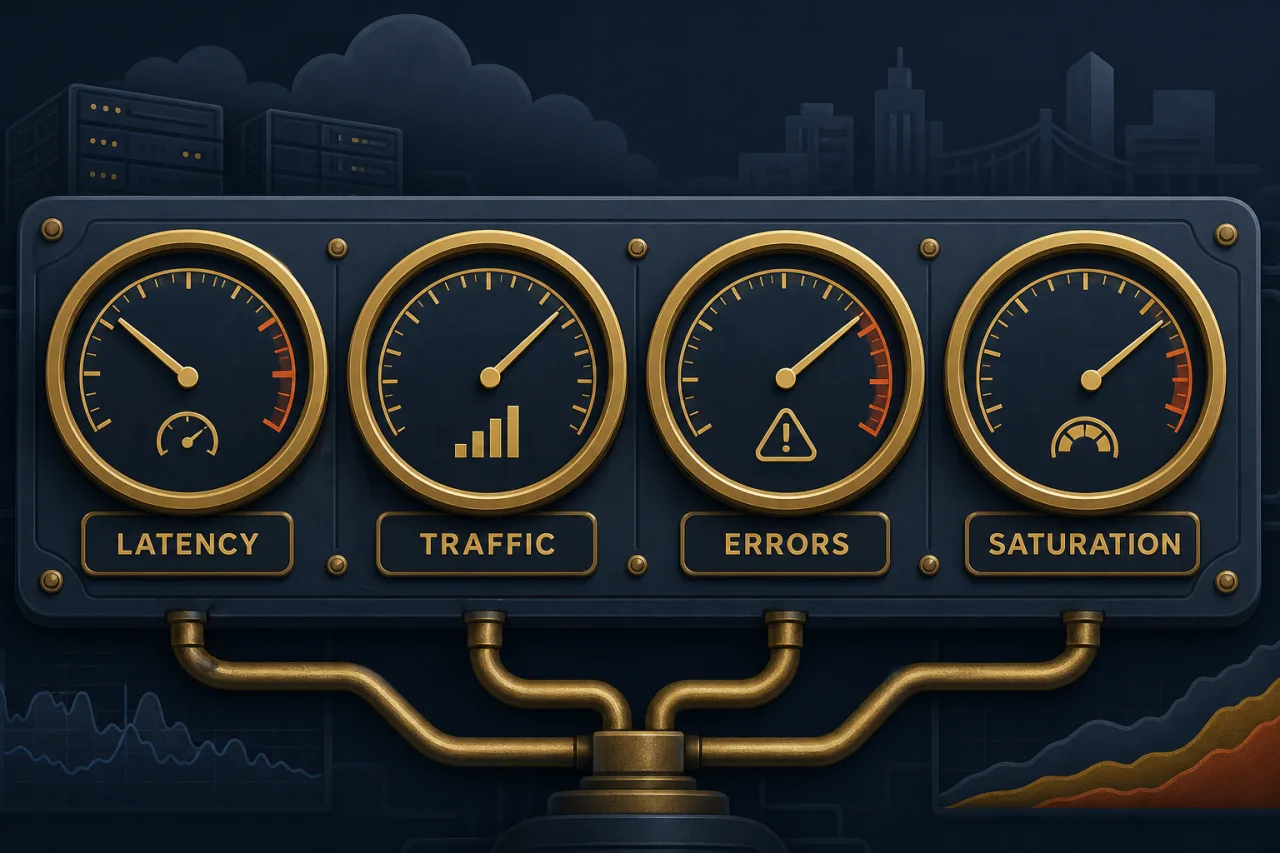
The Four Golden Signals of Monitoring
A practical guide to the four metrics Google SRE identified as the foundation of any production monitoring strategy: latency, traffic, errors, and saturation.
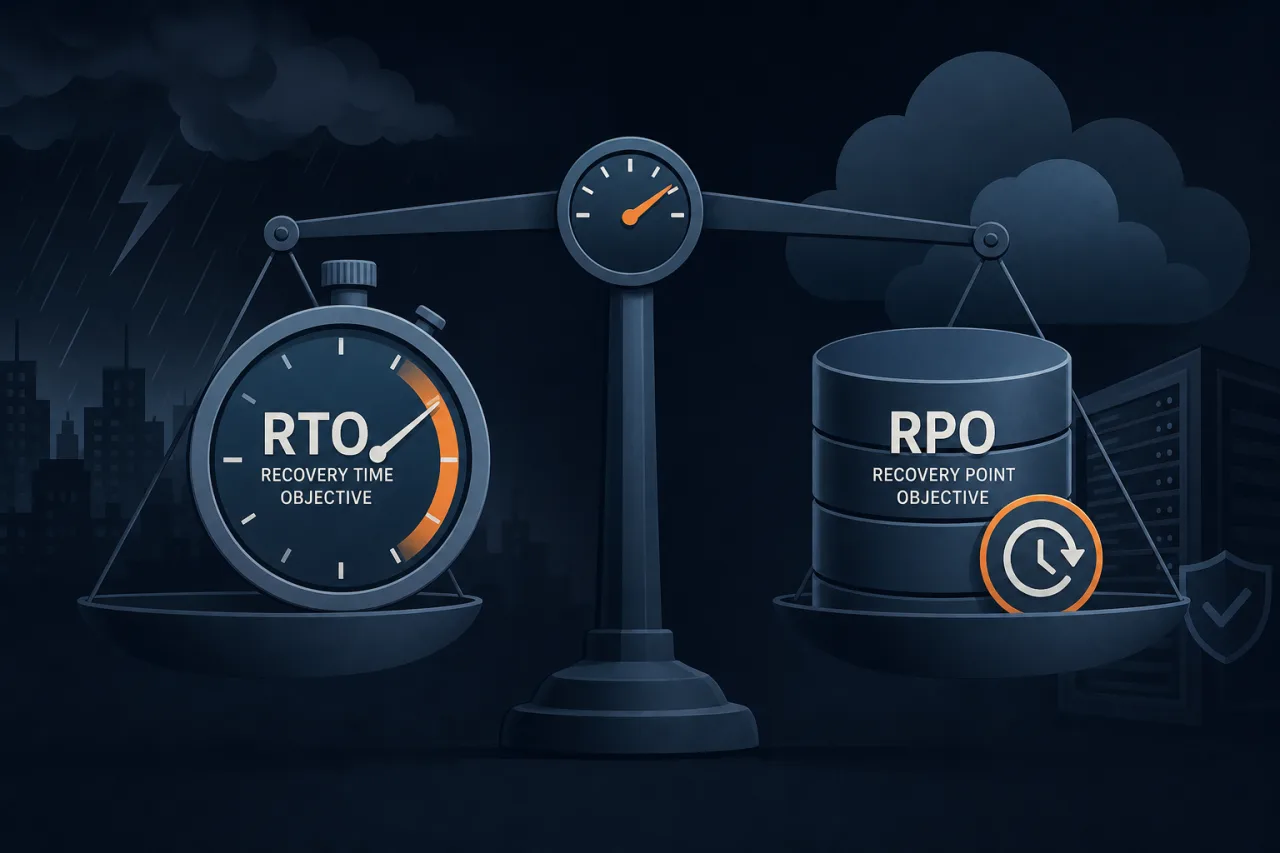
RTO vs RPO: Setting Recovery Targets That Match the Business
A practical guide to defining Recovery Time Objectives and Recovery Point Objectives that reflect what your business can actually tolerate — not just what sounds good in a runbook.
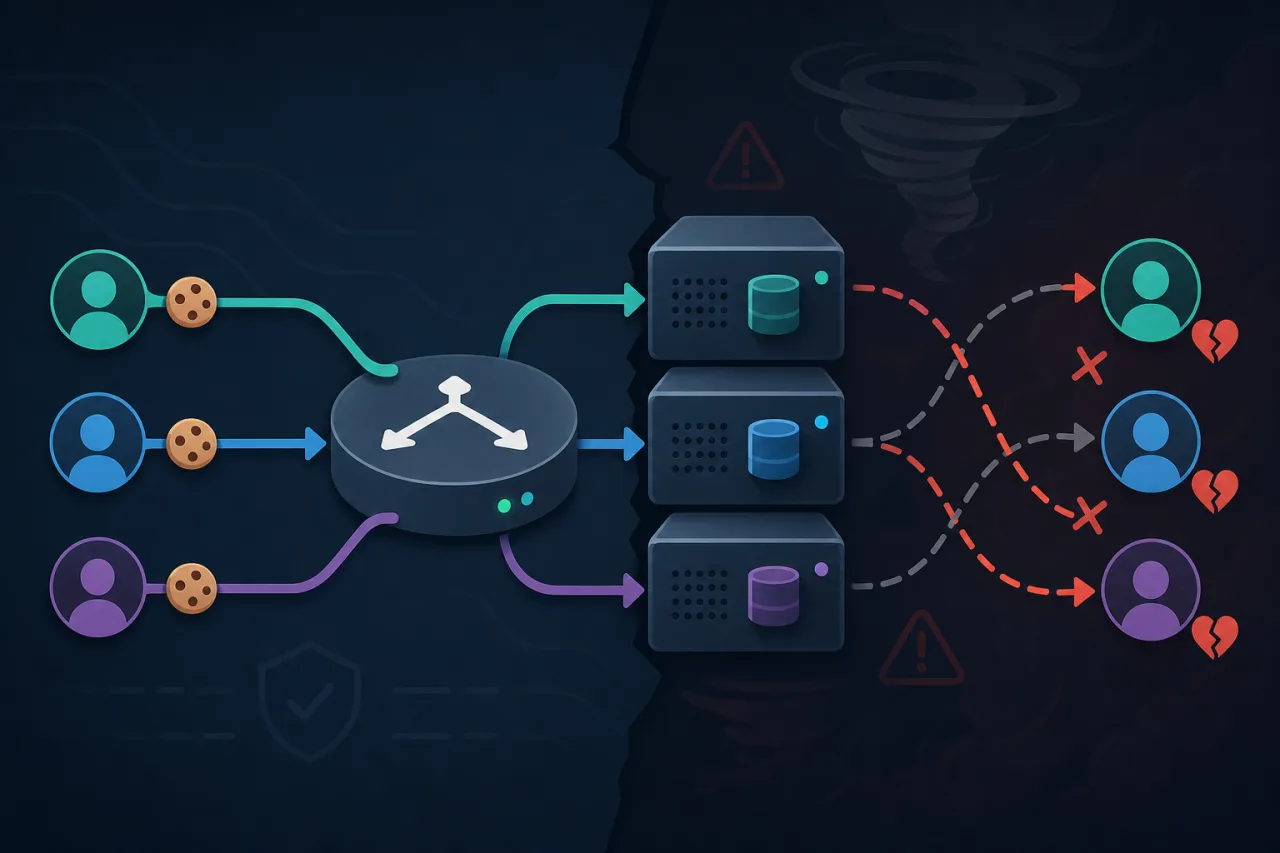
Sticky Sessions: When You Need Them and When They Hurt
A practical guide to understanding session affinity in load balancers — what problems it solves, what new ones it creates, and how to decide whether you actually need it.
Disaster Recovery as a Service (DRaaS): A Practical Primer
What DRaaS actually is, how it differs from backup, and what you need to set one up that works when it matters most.
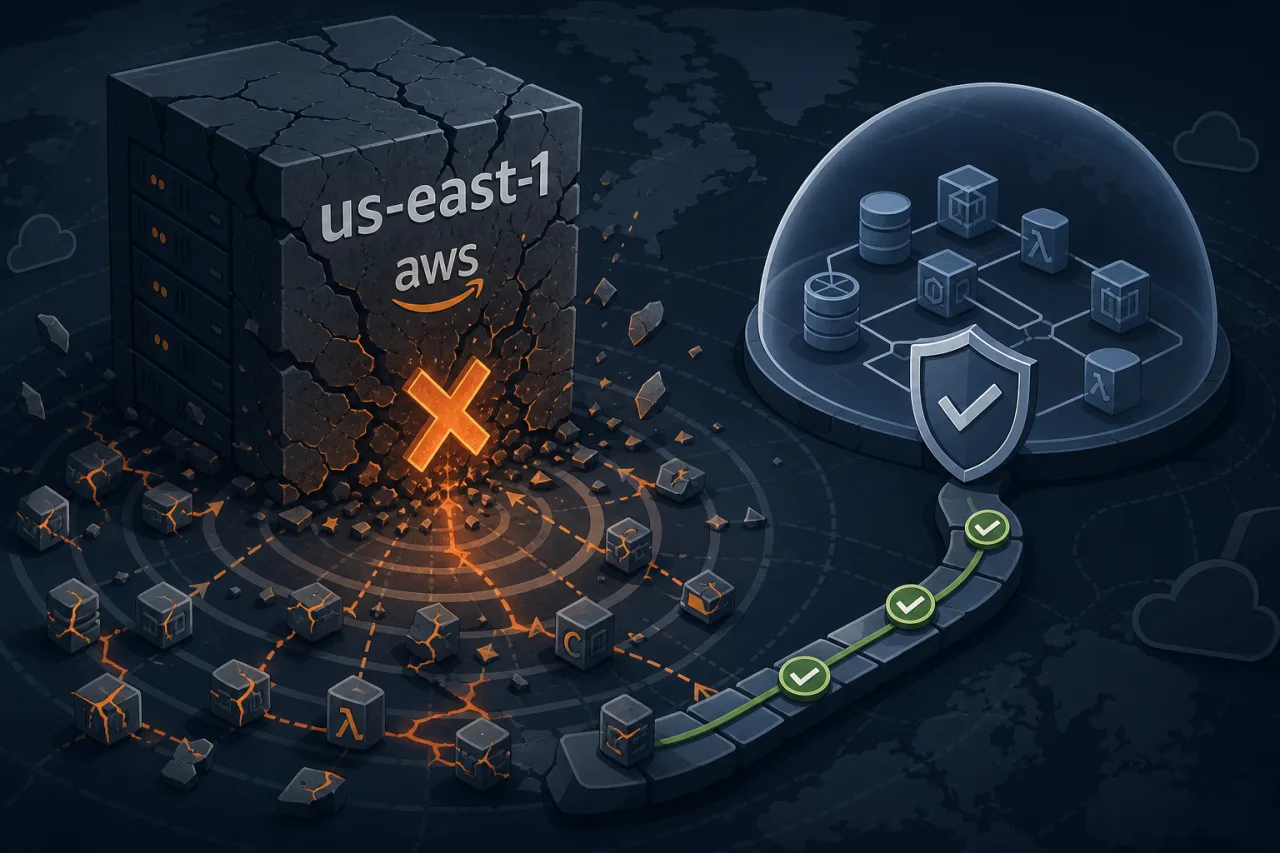
AWS Regional Recovery and Failure Boundaries
Map regional dependencies, prepare recovery capacity and data, and test the traffic switch without assuming that a second Region solves every failure.