Tutorials
Practical guides on uptime, monitoring, DRaaS, load balancing and AWS reliability from Pingy.io. Tracking an incident? See Outage Reports.
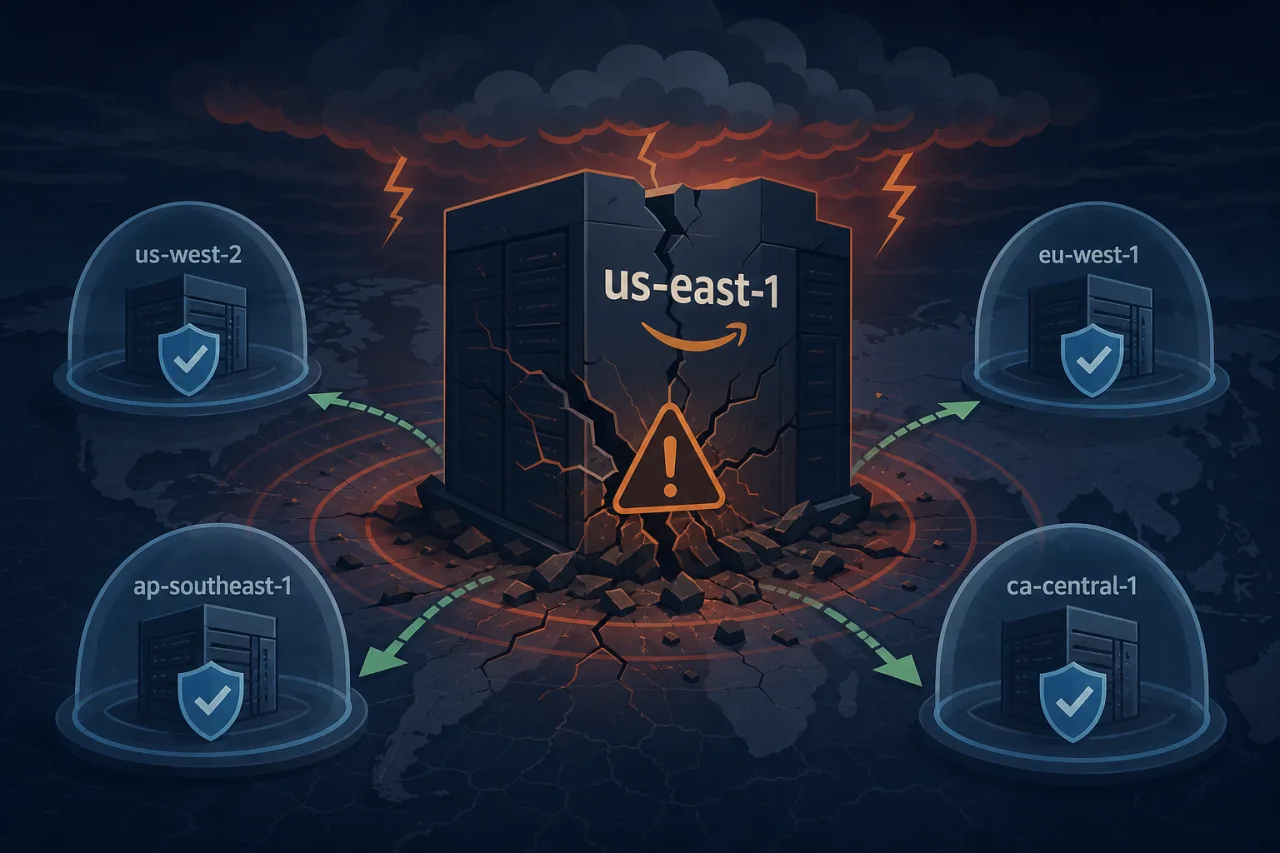
Why us-east-1 Fails the Most — and How to Avoid the Blast Radius
us-east-1 is AWS's oldest, busiest, and most failure-prone region — here's why that matters and what you can do to protect your systems.
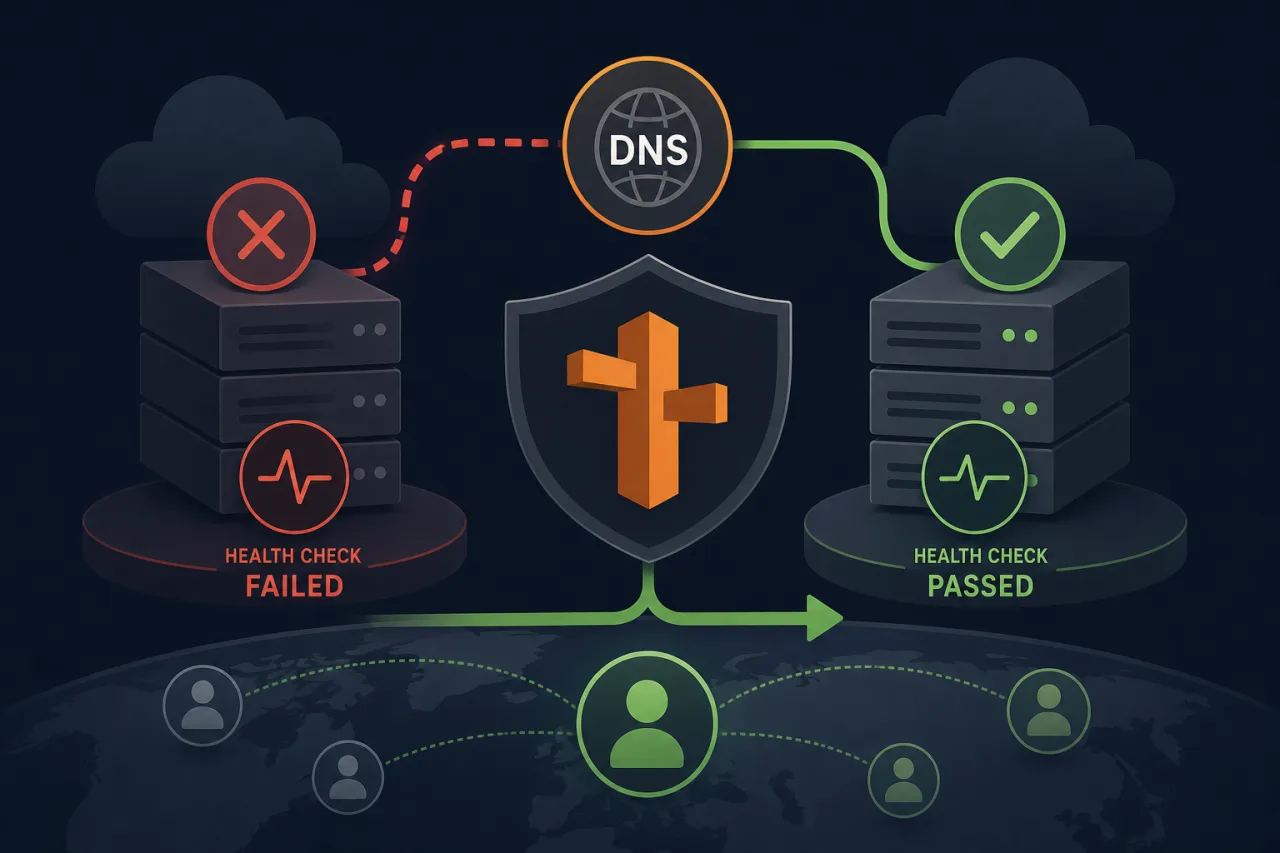
Route 53 Health Checks and DNS Failover: A Step-by-Step Guide
How to configure Route 53 health checks and DNS failover so traffic automatically reroutes when your primary endpoint goes down.
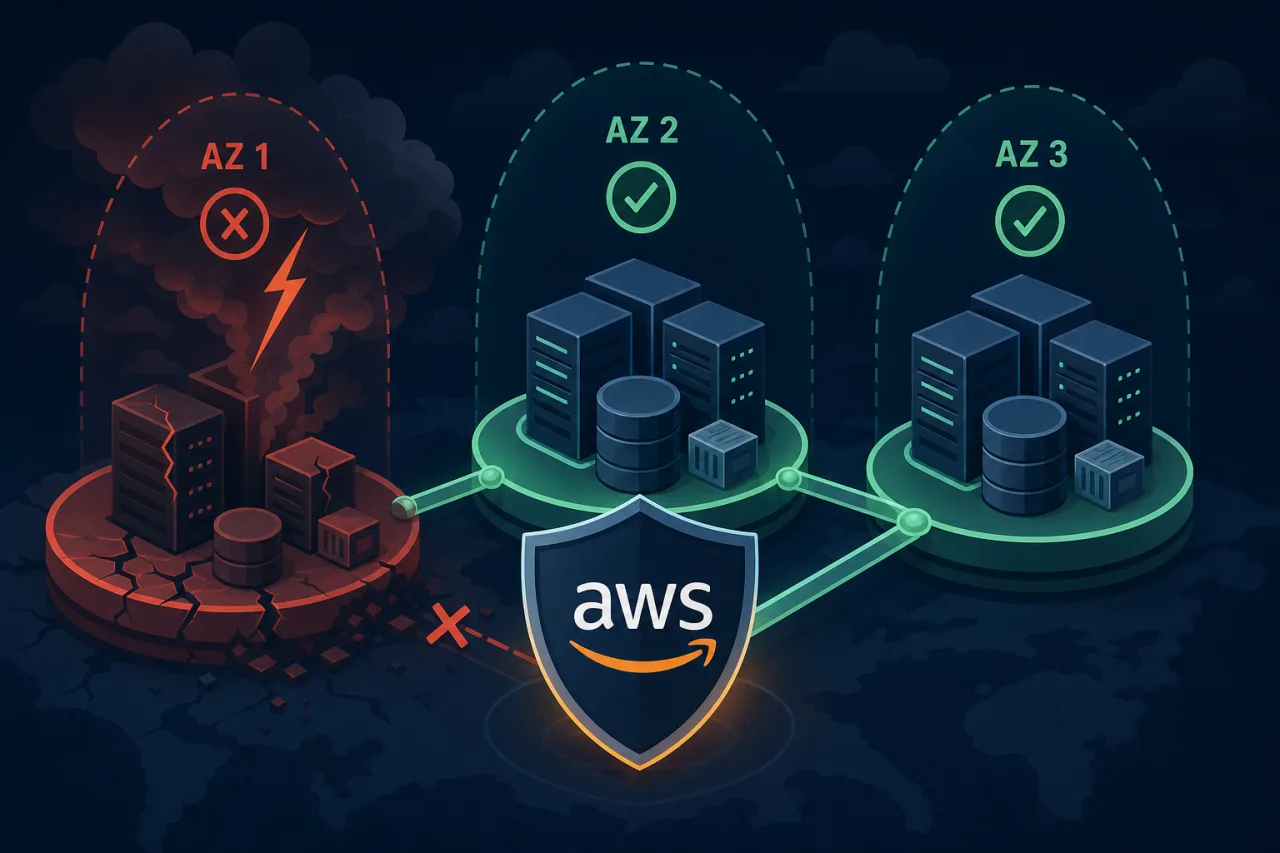
Surviving an AWS AZ Failure with Multi-AZ Design
A practical guide to architecting your AWS workloads across multiple Availability Zones so a single AZ outage doesn't take your service down.
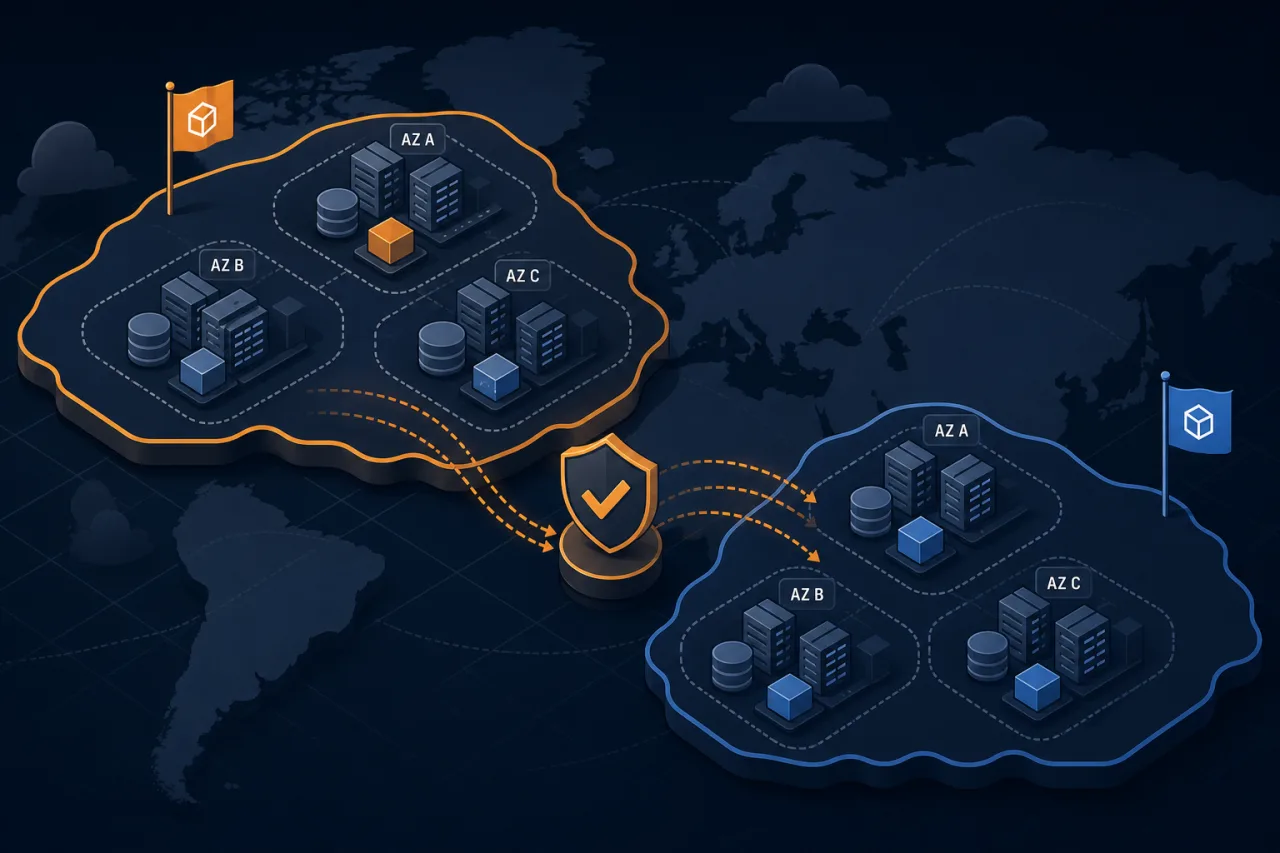
AWS Regions and Availability Zones: How to Architect Across Them
A practical guide to understanding AWS Regions and AZs, and the concrete patterns for building services that survive infrastructure failures.
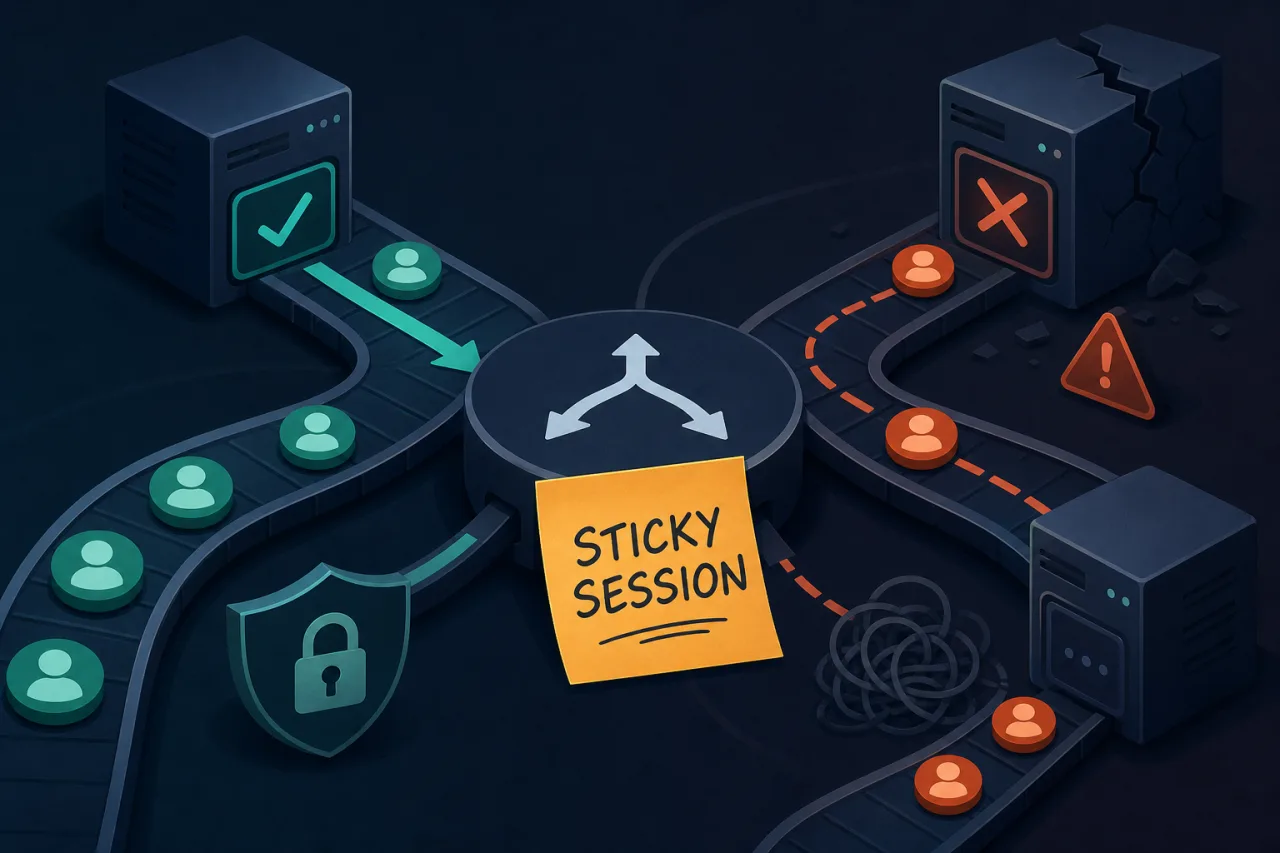
Sticky Sessions: When You Need Them and When They Hurt
A practical guide to understanding session affinity in load balancers—what problems it solves, what problems it creates, and how to decide whether you actually need it.
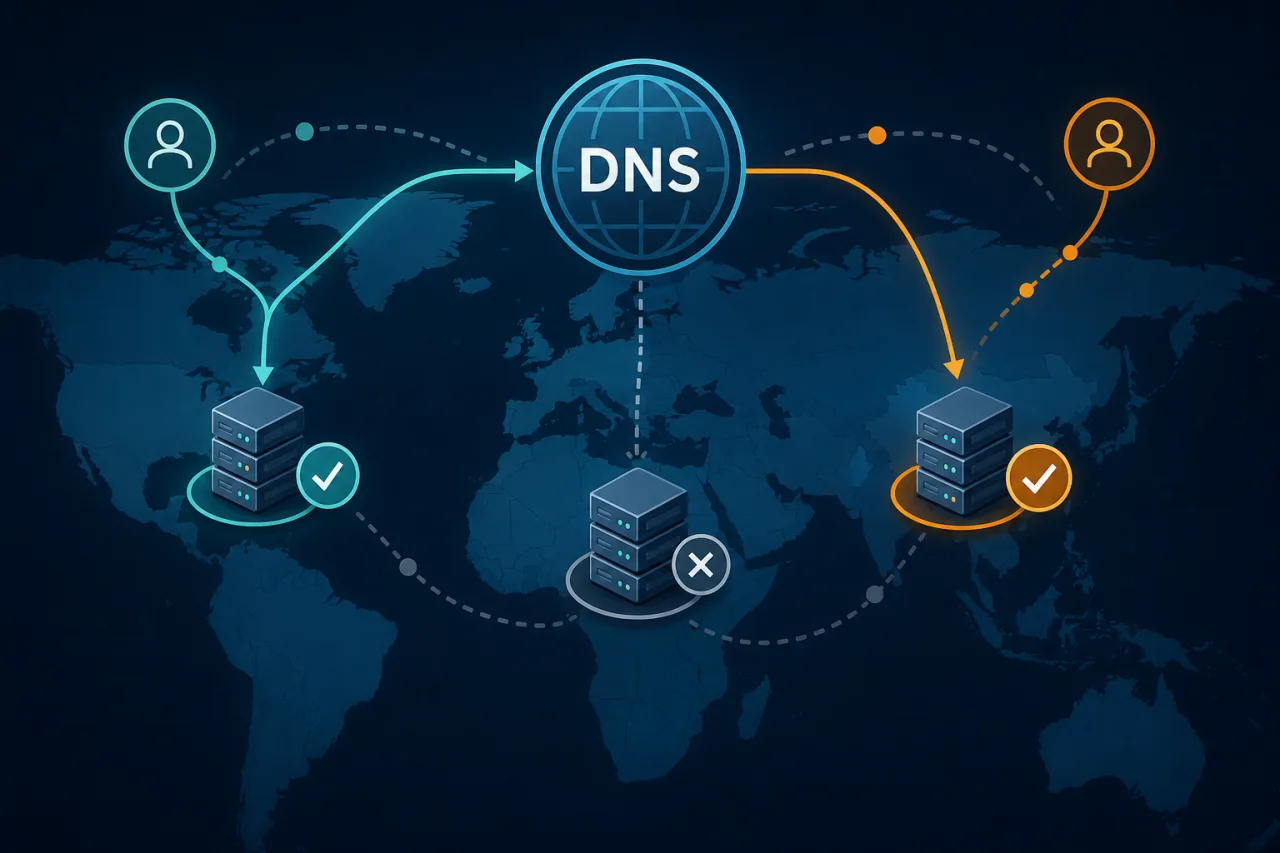
Global Server Load Balancing and Anycast DNS: How Traffic Finds the Nearest Healthy Node
A practical guide to GSLB and anycast DNS — how they work, when to use each, and what to watch out for in production.
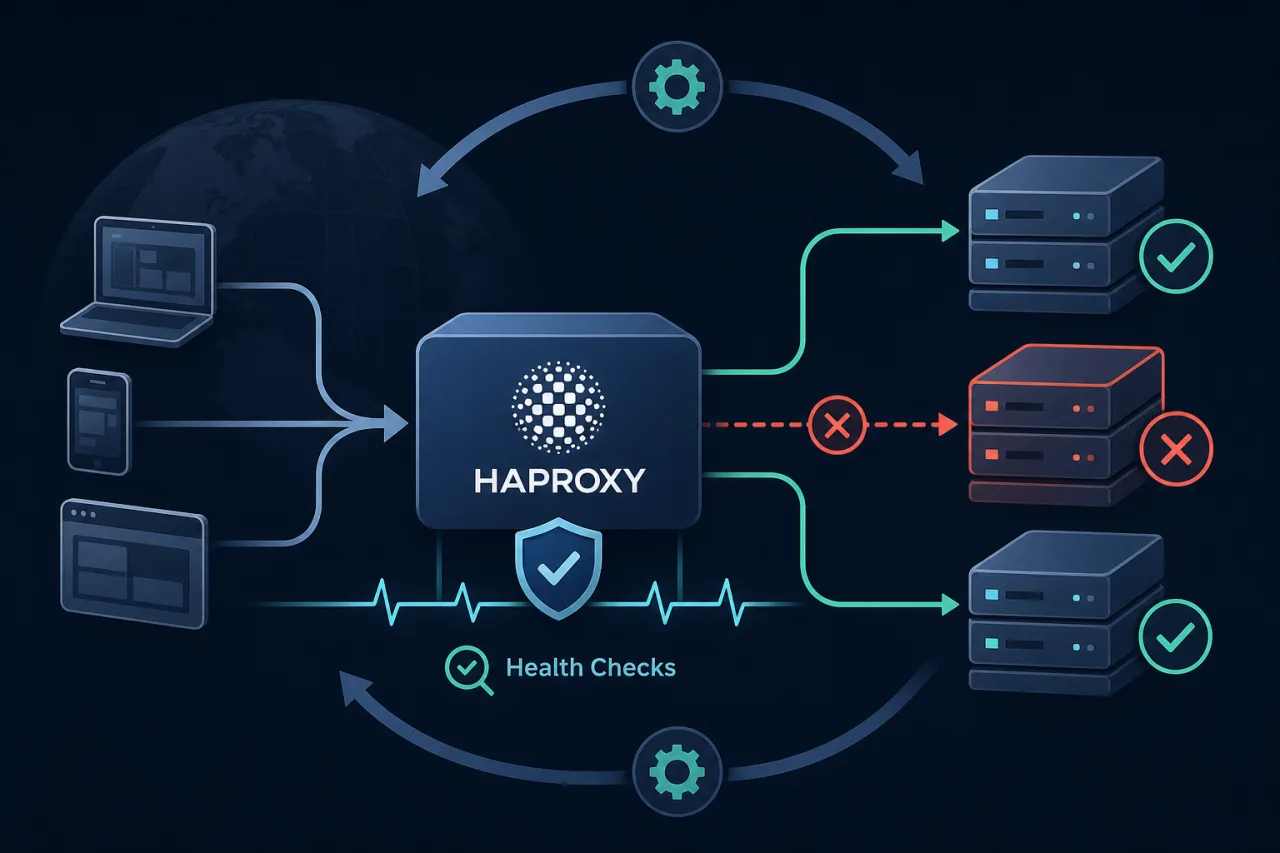
Health-Check-Based Failover with HAProxy
How to configure HAProxy's built-in health checks to automatically remove failing backends and restore them when they recover.
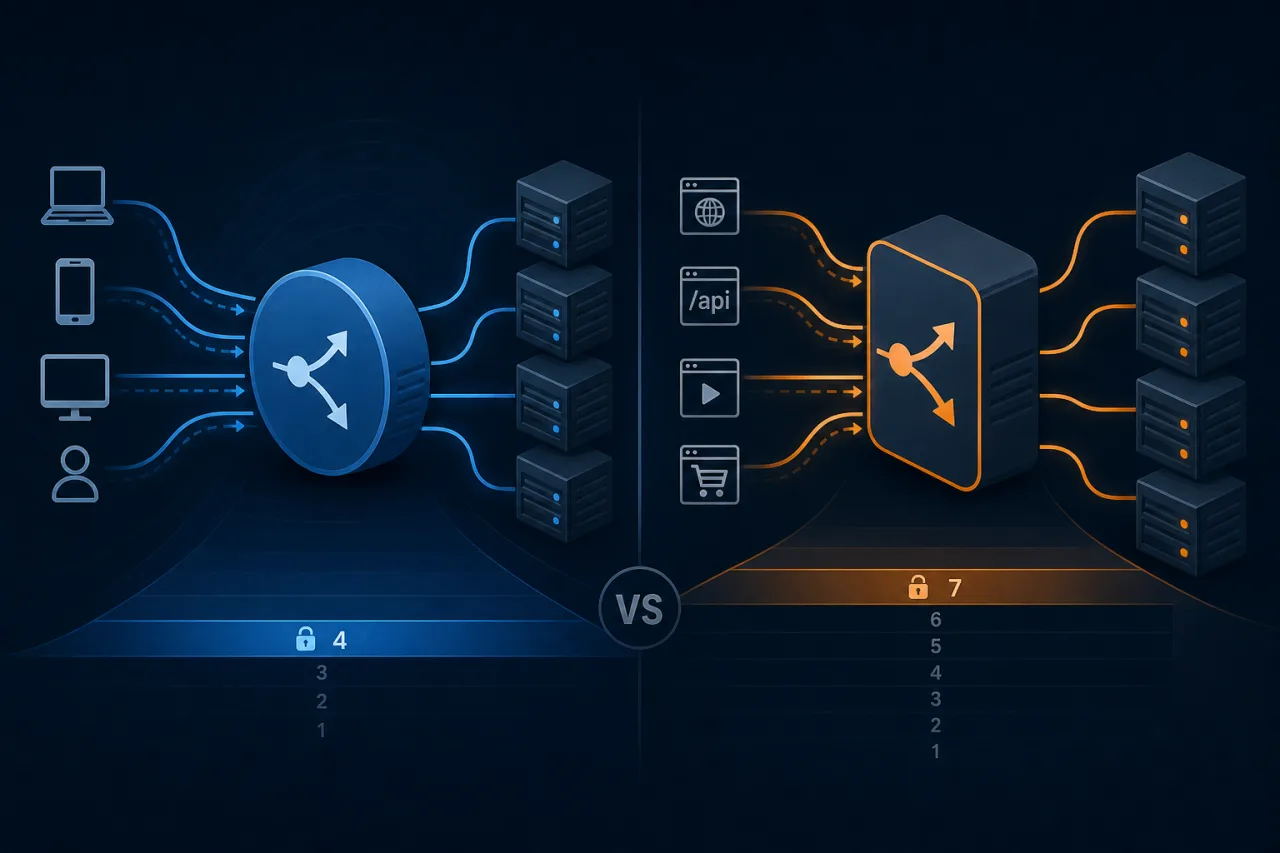
Layer 4 vs Layer 7 Load Balancing: A Practical Guide
Understand the real differences between transport-layer and application-layer load balancing so you can pick the right tool for your infrastructure.
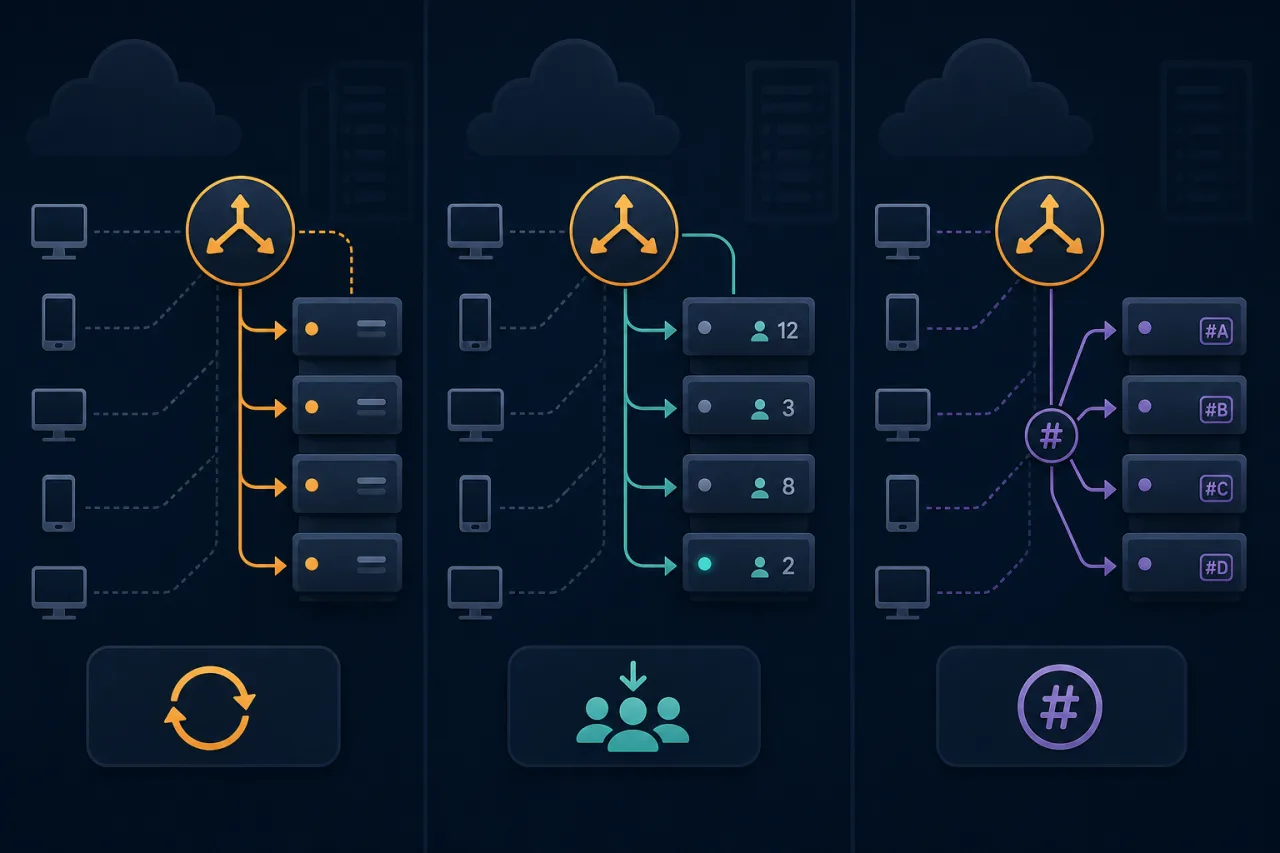
Load Balancing Algorithms Compared: Round-Robin vs Least-Connections vs Hashing
A practical breakdown of three core load balancing algorithms—when each one fits, where each one breaks, and how to choose the right one for your stack.
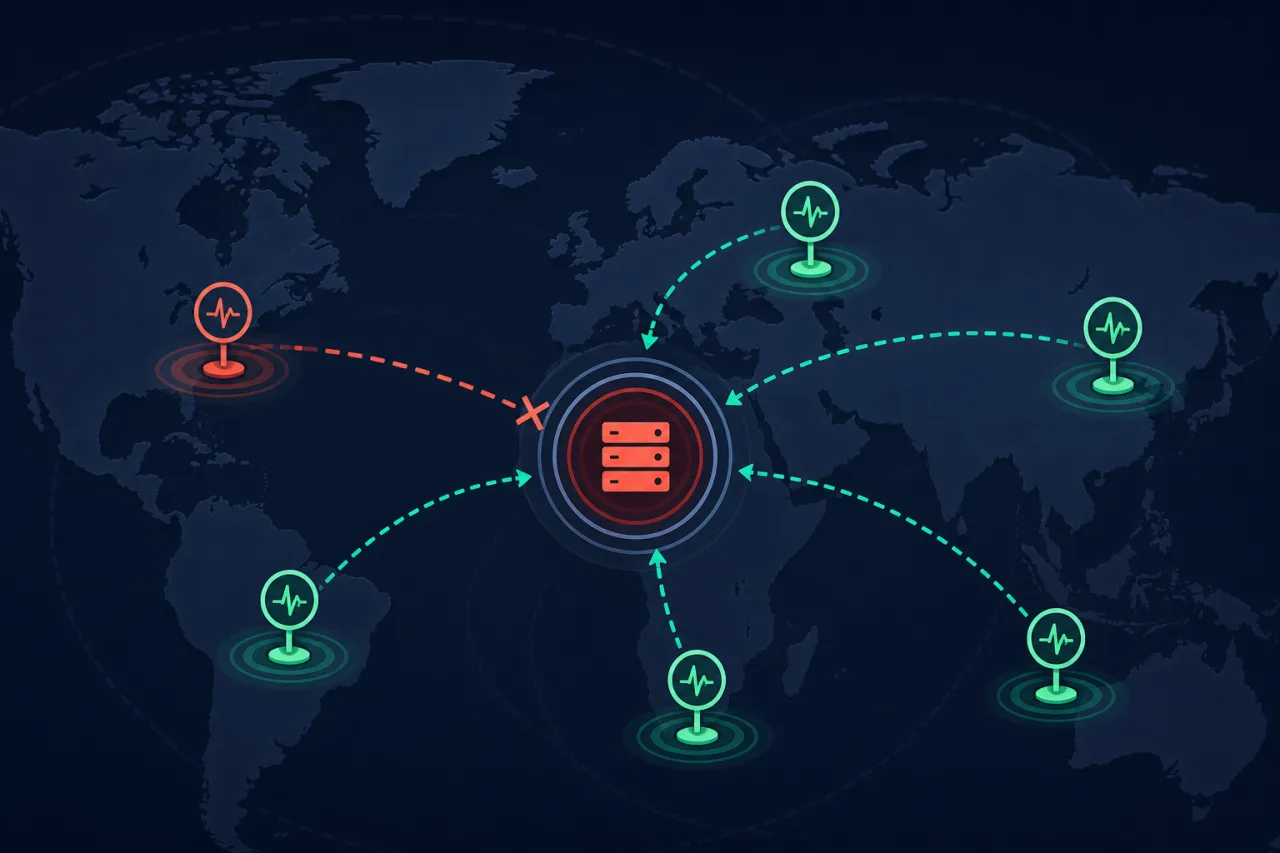
Why Multi-Region Monitoring Beats Single-Location Checks
A single monitoring probe gives you a single point of failure in your observability stack — here's why distributing checks across regions catches real outages that local monitors miss.
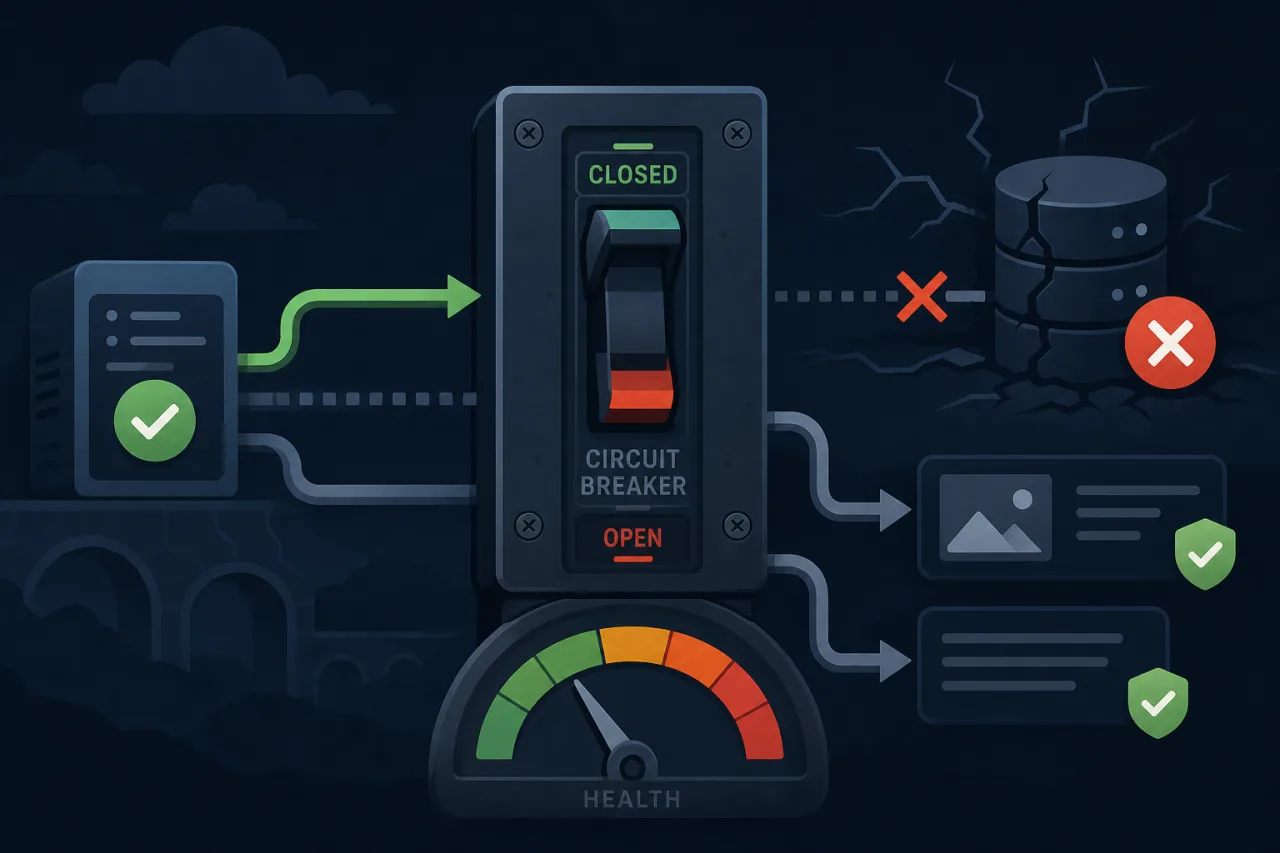
Graceful Degradation and the Circuit Breaker Pattern
How to keep your service partially alive when a dependency goes down, and how the circuit breaker pattern automates the decision to stop trying.
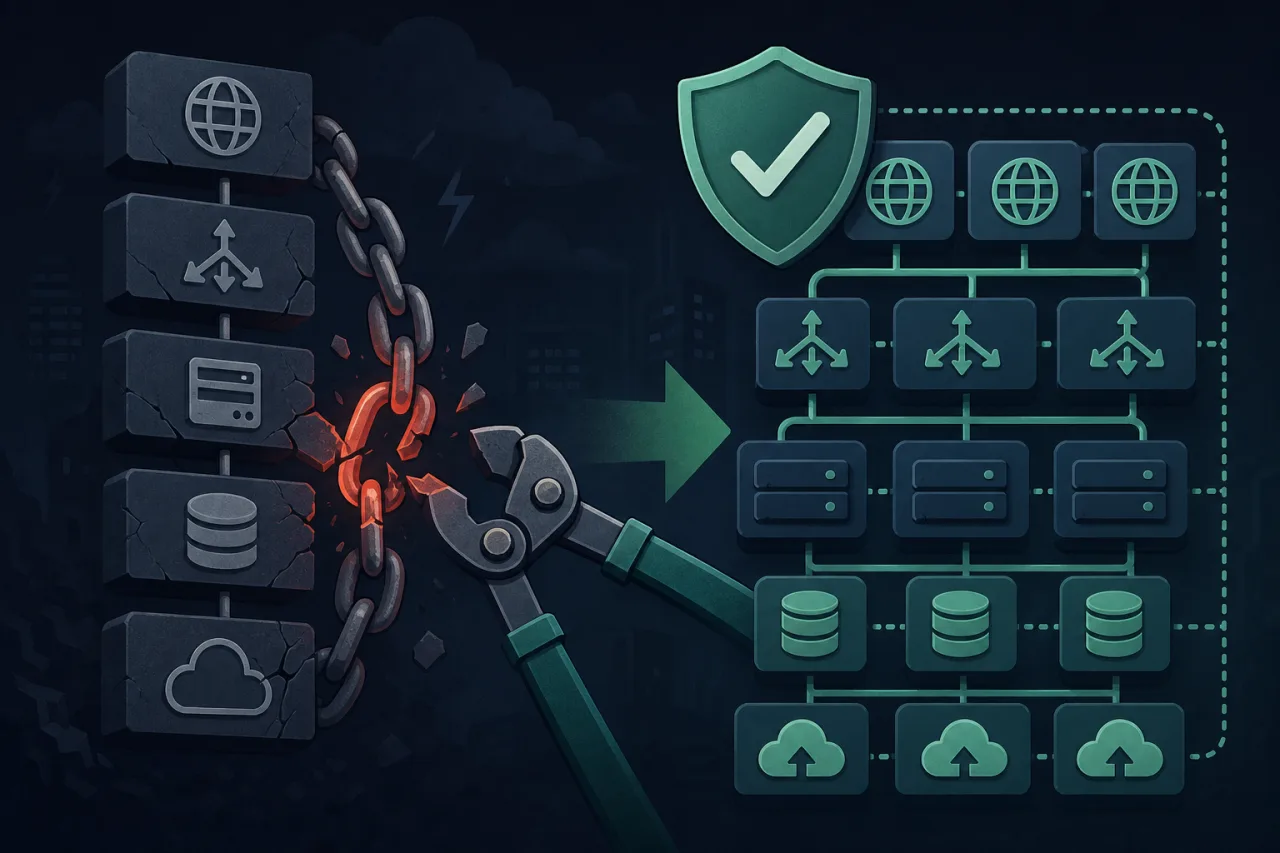
Eliminating Single Points of Failure in Your Web Stack
A practical walkthrough of where SPOFs hide in a typical web stack and how to engineer them out before they take your site down.